DZQJOKER/dsh-plugin-local-model
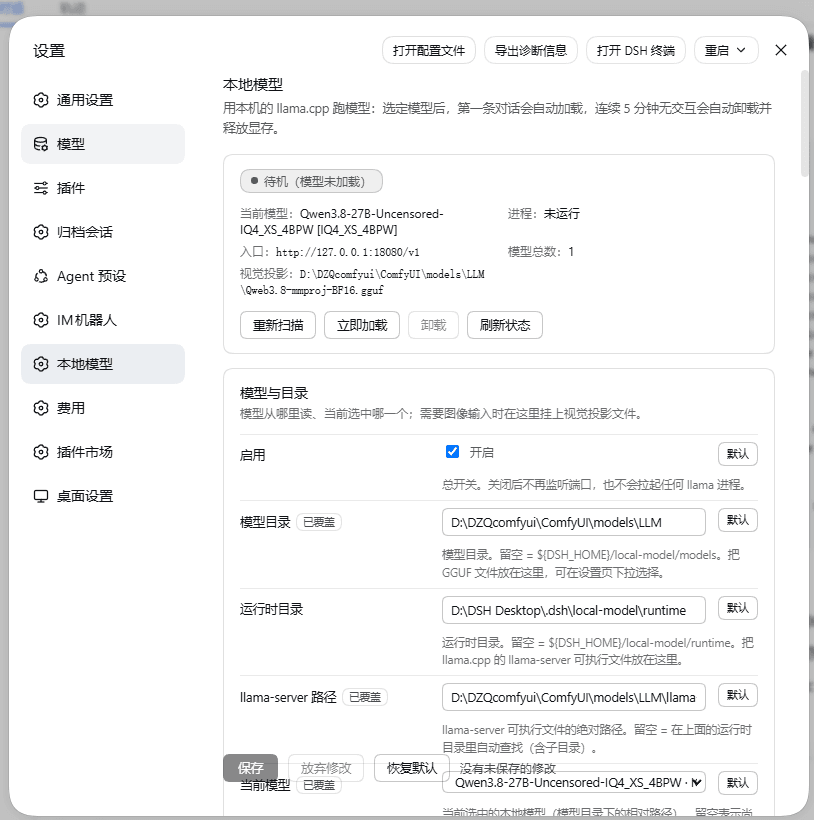
给 DeepSeek Harness(dsh) 用的本地模型插件:在设置里管理本地 GGUF 模型, 第一条对话自动拉起 llama.cpp 载入模型,连续 5 分钟无交互自动卸载并释放显存; 设置页顶部还有一块参数预设,把整套参数存成带名字的条目,一键切换。
catalog descriptioncatalog 简介 / catalog description:"DeepSeek Harness 本地模型插件:设置里独立的「本地模型」页,首条对话自动拉起 llama.cpp,空闲 5 分钟自动卸载释放资源。"
Project Overview项目介绍
dsh-plugin-local-model is a plugin built specifically for DeepSeek Harness (DSH): the repository name carries the dsh- prefix, the package.json declares dsh.bundle and dsh.client manifest fields plus a cordis patch, and the README positions the product as a DSH-native extension rather than a cross-agent tool. Its core capability is managing local GGUF models from DSH's settings panel, automatically launching llama.cpp on the first conversation and unloading the process after five minutes of idle time to release GPU memory. A named-parameter preset block at the top of the settings page lets users store full parameter sets as switchable entries, and recent releases also add an ffmpeg-aware WebP fix plus a startup-arguments panel that surfaces the exact command line handed to llama-server.
A typical workflow has the user download GGUF weights and a llama-server binary themselves, drop them into the directories the plugin specifies, pick a model and a parameter preset inside DSH, and start chatting. The plugin launches the server on demand, streams completions back into the DSH chat surface, retires the process on idle, and exposes a /local-model command plus a http://127.0.0.1:18080/local-model/status endpoint for runtime inspection. It targets DSH users who want a fully local LLM frontend without long-lived background inference eating VRAM.
Dependencies are user-supplied: the plugin never downloads models or llama binaries, listens only on the loopback interface, and ships nothing more than MIT-licensed client and server bundles built with esbuild around a self-replicated __ModuleLoader__ shim. Limits include one resident model at a time, configuration stored in a plugin-private JSON rather than settings.yaml (so credentials sync does not carry it), WebP vision requiring winget install Gyan.FFmpeg, kvmem-branch builds needing llama-kvmem-server.exe, and the settings panel only working over loopback access. First-run users should point the plugin at their model directory and llama executable before issuing the first chat.
dsh-plugin-local-model 是一款专为 DeepSeek Harness(DSH)打造的本地模型插件,仓库以 dsh-plugin 为主题、命名沿用 dsh-* 前缀,并在 package.json 中声明 dsh.bundle 与 dsh.client 字段及 cordis 补丁路径。功能上,它在设置面板管理本地 GGUF 模型,首轮对话自动拉起 llama.cpp 加载,连续 5 分钟无交互即卸载进程并释放显存;设置顶部另设参数预设区,可将整套参数存为带名字的条目一键切换。
典型流程是用户自行下载 GGUF 模型与 llama-server 可执行文件,放入插件指定目录,在设置页选定模型与命名预设后发起对话;插件负责拉起服务、流式转发请求、闲置回收,并提供 /local-model 命令查询运行状态。适合希望把 DSH 当作纯本地 LLM 前端、又不愿长期占显存或手动管进程的本地推理用户。
依赖方面,模型与 llama 工具链全部由用户提供,插件不联网下载;除 127.0.0.1 回环端口外不监听任何外部端口;视觉投影需额外安装 ffmpeg,kvmem 分支需用 llama-kvmem-server.exe。限制包括同时只能驻留一个模型、设置存于插件私有 JSON 而非 settings.yaml、WebP 图像依赖 ffmpeg、面板仅在回环访问时可用;许可为 MIT,首次使用请先在设置页指定模型路径与可执行文件。
请帮我安装这个 DSH 插件。安装前先完成【兼容性检查 + 安全性检查】,检查通过再动手。

插件:dsh-plugin-local-model(DZQJOKER/dsh-plugin-local-model)
仓库:https://github.com/DZQJOKER/dsh-plugin-local-model
本站详情页:https://www.yhbd.top/plugins/dzqjoker-dsh-plugin-local-model/
本站登记:类型 plugin · 归类 原生 DSH 插件 · 许可证 MIT · ⭐ 3 · 最近提交 2026-09-29 · 主语言 JavaScript

按下面顺序执行,每步先把结论告诉我,再进入下一步:

【1 兼容性检查】
① 我这边:DSH 版本、Node 版本、操作系统、当前 profile(web / desktop)。
② 读它的 README、package.json、插件 manifest,列出它要求的 DSH 版本 / Node 版本 / 操作系统 / 外部依赖 / 需要另外先装的运行时。
③ 逐条比对,结论只写「满足 / 不满足 / 未知」三种;不满足的给出可行替代方案。
④ 检查是否和我已装的插件冲突:命令名重复、skill / tool 重名、端口占用、重复注册的 MCP server。

【2 安全性检查】
① 仓库可信度:和上面「本站登记」是否一致;star / fork 数、创建时间、最近提交,是否归档或长期停更。
② 安装脚本:逐行看 package.json 的 preinstall / install / postinstall,以及 install.sh、setup.ps1 之类脚本。出现 curl|bash、下载后直接执行、混淆代码、访问与插件功能无关的域名,立刻停下来告诉我,不要继续装。
③ 依赖:列出新增依赖,标出无人维护、或与知名包拼写近似的可疑包(typosquatting)。
④ 权限与副作用:它会读写哪些目录、访问哪些域名、需要哪些 DSH 权限(filesystem / network / shell / clipboard 等),以及怎么卸载和回滚。
⑤ 如果它要求 sudo / 管理员权限,或权限明显超出功能所需,先停下来问我。

【3 安装】
上面两步没有「不满足」和「高危项」时才执行;用官方推荐方式安装,不要自行提权。

【4 汇报】
用表格输出:检查项 / 结论 / 依据 / 是否需要我决策。拿不准的一律写「未知」并说明要我怎么确认——不要猜,也不要替我决定。
Send this message to DSH in your current session: it verifies compatibility and security first (answering met / not met / unknown item by item) and only installs once everything checks out — it will stop and ask you if it finds a high-risk item. The box scrolls; the copy is the full prompt. CLI install commands may not be accurate across systems, so DSH is the safer route.把上面这条消息直接发给当前会话里的 DSH:它会先核对兼容性与安全性(逐条给「满足 / 不满足 / 未知」),确认没问题再安装,有高危项会停下来问你。框内可滚动,复制到的是完整提示词;安装命令不一定准确,发给 DSH 更稳。
- Only 3 stars - very few users, little community feedback星标只有 3,几乎没人在用,遇到问题缺少社区反馈
DSH walks through these 9 checksDSH 会逐条核对这 9 项
Compatibility兼容性
- DSH, Node, OS and profile requirementsDSH 版本 / Node 版本 / 操作系统 / profile 是否满足要求
- External dependencies and runtimes (Electron / Python / Docker, ...)外部依赖与运行时(Electron / Python / Docker 等)是否齐备
- Conflicts with installed plugins: command names, skill / tool names, ports, duplicate MCP registration与已装插件是否冲突:命令名、skill / tool 重名、端口占用、重复 MCP 注册
Security安全性
- Repo matches the facts registered here; archived or abandoned?仓库是否与页面登记一致,是否归档或长期停更
- Safety of preinstall / install / postinstall and install.sh / setup.ps1preinstall / install / postinstall 与 install.sh、setup.ps1 是否安全
- curl|bash, download-then-execute, obfuscation, unrelated domains → stop immediatelycurl|bash、下载即执行、混淆代码、无关域名 → 立刻停止
- Typosquatting or unmaintained packages among the new dependencies新增依赖里有没有 typosquatting 或无人维护的包
- Requested permissions vs. what the feature actually needs申请了哪些权限、是否超出功能所需(filesystem / network / shell / clipboard)
- Any sudo / admin requirement, plus uninstall and rollback是否要求 sudo / 管理员权限,以及卸载与回滚方式
Anything uncertain must be marked unknown with a note on how to confirm it. This site's signal screen is a static snapshot, not a security audit.拿不准的必须标「未知」并说明要我怎么确认。本站的信号筛查是静态快照,不能替代安全审计。
Or use CLI install (for developers)或使用命令行安装(适合开发者)
CLI Install命令行安装
dsh plugin --profile desktop add github:DZQJOKER/dsh-plugin-local-model把 DZQJOKER/dsh-plugin-local-model 加入你的 DSH 配置(web profile)即可启用。
READMEREADME

dsh-plugin-local-model
给 DeepSeek Harness(dsh) 用的本地模型插件:在设置里管理本地 GGUF 模型, 第一条对话自动拉起 llama.cpp 载入模型,连续 5 分钟无交互自动卸载并释放显存; 设置页顶部还有一块参数预设,把整套参数存成带名字的条目,一键切换。
模型和 llama 工具由用户自己下载,放进插件规定的目录即可 —— 插件不联网拉模型、不碰工作区文件、 除本机回环地址外不监听任何端口。
更新日志
0.7.0 — ① 修掉「装上视觉投影文件后一直报 400
Failed to load image or audio file」。根因不在插件、也不在模型:llama.cpp 内置的图像解码器只认 png / jpeg / gif / bmp 这些老格式,不认识 WebP;遇到 WebP 它会去起外部的ffprobe探测、ffmpeg转码,而这两个是从 PATH 里找的(这个构建砍掉了--ffmpeg-path,只剩 PATH 一条路)。机器上没装 ffmpeg 时,服务端会打probe: failed to launch ffprobe/failed to decode webp buffer,客户端拿到 400 —— 而同一批里的 JPEG 却能正常识别(dsh 转码时两种格式都会产出,实测.dsh/attachments/v1/request-images/下两种都有),所以表现是「时好时坏」,极易被当成插件或模型坏了。现在:插件会自动找到 ffmpeg 并把它的目录前置进 llama-server 子进程的 PATH(不必改系统 PATH、也不必为此重启 dsh),找不到且已开视觉时会打出一条说清「哪个格式会失败、为什么只有它、怎么修」的警告。装法:winget install Gyan.FFmpeg。 ② MTP 与视觉投影从「互斥」改为「可共存」(新增设置项mtpWithVision,默认开启)。原规则来自上游 llama.cpp(两者同时下发会加载失败),但 kvmem 分支的llama-kvmem-server实测支持:同时给--mmproj与--spec-type draft-mtp时clip_model_loader: has vision encoder与creating MTP draft context会同时出现、服务正常起来、看图对话也能识别(2026-09-21 本机验证)。换回官方 llama.cpp 的用户把这个开关关掉即恢复旧的互斥行为(MTP 生效、--mmproj被忽略并给出说明)。 ③ 设置页顶部新增「本次启动参数」面板:把这次真正下发给 llama-server 的完整命令行逐项一行列出来(不是设置页里填的那一份 —— 两者之间隔着门控跳过、构建默认值与自动收敛),配一张参数摘要(含派生的「GPU KV 合计 = 工作集 + 解码预留」)、一条「复制命令行」按钮、以及被跳过的选项与识别表没覆盖到的选项(后者过去只躺在日志里)。刷新跟随运行状态轮询,换模型/改参数后自动更新。0.6.0 — ① 补齐 kvmem 分支(
kvmem/kvmem-llama.cpp)的全部缺失启动参数,共 31 项:KVMem 家族 18 项(--kvmem/--kvmem-budget/--kvmem-gen-reserve/--kvmem-block-tokens/--kvmem-sink-tokens/--kvmem-recent-tokens/--kvmem-method/--kvmem-query-last/--kvmem-query-max-tokens/--kvmem-query-replay/--kvmem-query-policy/--kvmem-mtp-state/--kvmem-gpu-ratio/--kvmem-cpu-gb/--kvmem-nvme-gb/--kvmem-nvme-dir/--kvmem-harvest-v/--kvmem-raw-k-nvme)、外加-n/--n-predict、-lm/--load-mode、--kv-dtype、--spec-kv-dtype、--spec-draft-n-max、--spec-draft-p-min、--frequency-penalty、--mmproj-offload、--chat-template-file、--chat-template-kwargs、--reasoning-effort、--reasoning-budget-message。默认值一律是「不下发」(数字项用-1当哨兵、字符串用空串),所以装官方 llama.cpp 的部署行为一字不变;kvmem 专有项走严格门控,探测不到就整体跳过并在日志里说明。 ② 新增「输出上限溢出保护」(guardContextOverflow,默认开启)。上游 llama.cpp 遇到prompt + max_tokens > n_ctx只打一条 warning 再自行收敛,而 kvmem 那个独立 server 是硬拒绝:HTTP 400 {"error":"prompt + max_tokens exceeds n_ctx"}—— 报错里既没有 prompt 长度也没有 n_ctx,用户只能乱试。现在代理会先把「必然失败」(max_tokens >= n_ctx,任何非空提示词都放不下)的上限预防性压到n_ctx − 1024,再对服务端明确拒绝的请求逐级减半重试(只缓冲 400,其余状态码照旧流式直通,正常对话零额外开销);实在装不下时把原文换成一句带上真实n_ctx与最可能原因的中文说明。 ③ 新增加载期配置一致性提醒:maxTokens不小于ctxSize(本轮线上故障的根因)、超过一半、或--kvmem-gen-reserve小于单次输出上限时,加载日志里直接点明后果与建议值。 ④ 修掉一处静默缺陷:被跳过选项的汇总提示原先在采样参数之后就结算了,导致后面新增的每一项(--kvmem-*/-n/-lm…)被跳过后都不会出现在日志里。 ⑤ 新增「KVMem 分块缓存」与「多 Token 预测(MTP)细节」两个设置分组。
Showing the opening section of the README — the full document lives in the repository以上为 README 开头摘要,完整文档在仓库内 · View the full README on GitHub →在 GitHub 查看完整 README →
Related相关推荐
- ranxianglei/billion-context 基本稳定可用 A context-compression plugin for small context windows (a 100K context is enough), token savings (5x fewer tokens…
-
 liangmianya/dsh-synapse
A visual, non-linear conversation workspace plugin for DeepSeek Harness ; A canvas-based session explorer and branching …
-
 alaliqing/claude-paper
📖 Cross-agent research paper toolkit for Claude Code, Codex, OpenCode, and DeepSeek Harness—quick summaries, deep study…
-
 acryldev/acryl
ACRYL - Agent Context Relay Yielding Lifecycles. One persistent workspace, one canonical context, any coding agent.
-
 omdsh-dev/dsh-annotation
DSH Web 选中批注插件:选文字→批注→回车随消息发送;气泡隐藏批注块(零闪烁);回复按 Annotation N 逐条对照(可悬浮芯片)。官方 bundle,零核心改动
-
 Anionex/dsh-turn-rewind
deepseek harness对话和代码状态回退插件 | DSH — rewind conversation and workspace state, powered by a persistent Change Ledger
-
 Tyan66666/billion-context-dsh
Model-driven context management (Active Context Pruning / ACP) for the DeepSeek Harness — the model decides when and wha…
-
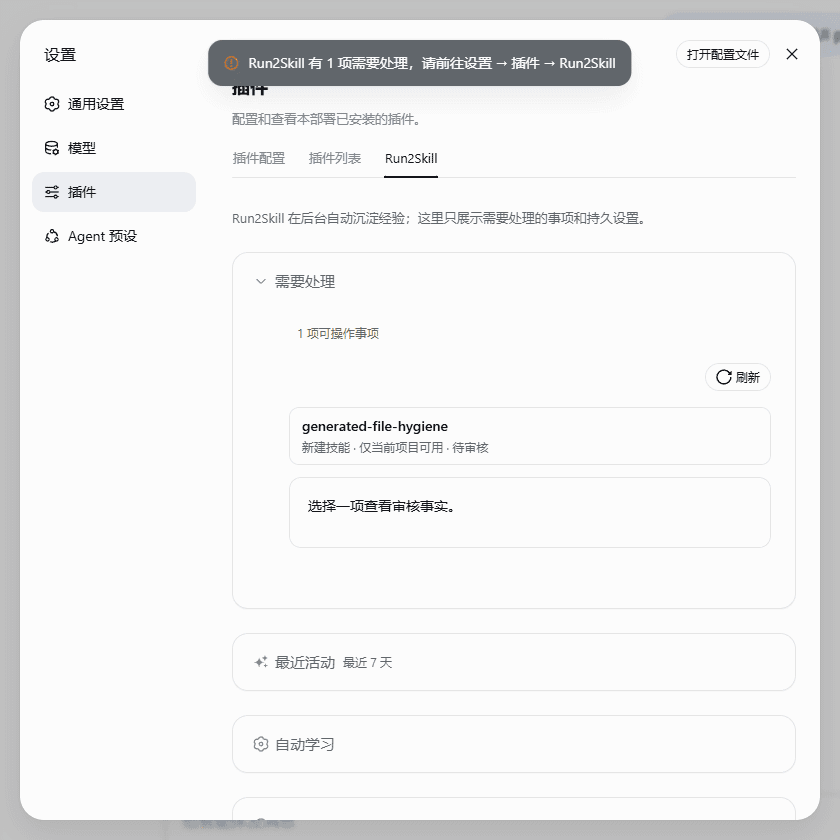 qkycir-123/dsh-run2skill
Automatically turn successful DeepSeek Harness sessions into reusable, reviewable Agent Skills.