Yunado/dsh-qwen38-local-qol
DeepSeek Harness QoL plugin for the local Qwen3.8 line (27B/Flash-Next): per-request thinking budgets, a compaction backend that stops burning the output cap on thinking, and a settings tab. 本地 Qwen3.8 线的 DSH QoL 插件:逐请求 thinking 预算、不再把输出帽烧在 thinking 上的压缩后端、设置 tab。
Project Overview项目介绍
This is a QoL plugin for DeepSeek Harness, designed for users running Qwen3.8 locally via OpenAI-compatible APIs. It adds per-request thinking budgets and an optimized compaction backend that prevents thinking content from wasting output caps. No core patches required, only works with local Qwen3.8 services.
这是DeepSeek Harness的QoL插件,针对本地运行Qwen3.8系列模型的场景,提供按请求推理预算、优化压缩后端避免思考内容占用输出额度,自带设置面板无需修改核心,仅兼容本地OpenAI兼容API的Qwen3.8服务。
请帮我了解并安装插件:【dsh-qwen38-local-qol】【https://github.com/Yunado/dsh-qwen38-local-qol】Send this message to DSH in your current session. CLI install commands may not be accurate across systems — DSH will figure it out for you.把上面这条消息直接发给当前会话里的 DSH,让它帮你了解并安装。安装命令不一定准确,发给 DSH 更稳。
Or use CLI install (for developers)或使用命令行安装(适合开发者)
CLI Install命令行安装
dsh plugin --profile web add github:Yunado/dsh-qwen38-local-qol把 Yunado/dsh-qwen38-local-qol 加入你的 DSH 配置(web profile)即可启用。
READMEREADME
dsh-qwen38-local-qol

A QoL plugin for DeepSeek Harness (DSH) for running Qwen3.8 locally (llama.cpp llama-server, NInfer, or TabbyAPI — the ExLlamaV3 backend server; all serve the OpenAI-compatible /v1 API; at the config level also Qwen3.8-Flash-Next). No core patches, no pi-ai patchfile.
Install
dsh plugin --profile web add github:Yunado/dsh-qwen38-local-qol
Restart dsh web: at boot the plugin generates the qwen38 user preset from the standard preset's composition, and sets it as the default agent preset when no default is configured. New sessions use it automatically; existing sessions keep the preset they were created with.
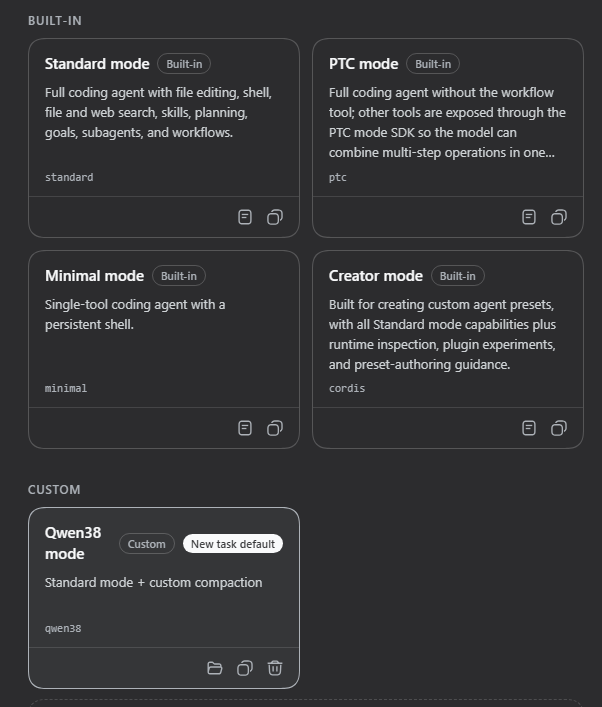
What it supports
- Per-request thinking budgets. The llama.cpp line sends the selected per-effort budget on every request (
reasoning_effort+reasoning_budget_tokens— overrides the server's--reasoning-budget); the NInfer engine reads its single thinking budget from the server startup flag (--default-thinking-budget) — the settings tab shows that as a note on the NInfer line (no input), whiledefaultThinkingBudgetstays valid as a headless/env config field; the TabbyAPI line accepts both natively, so per-effort budgets ride every request. - A compaction backend. The summarizer's prefill is trimmed (recent reasoning only, images downgraded to text placeholders, tool results capped), and compaction calls run thinking-off at the line's full output cap — checkpoints stop getting truncated at the token cap.
- A settings tab that configures both lines, live.
The settings tab
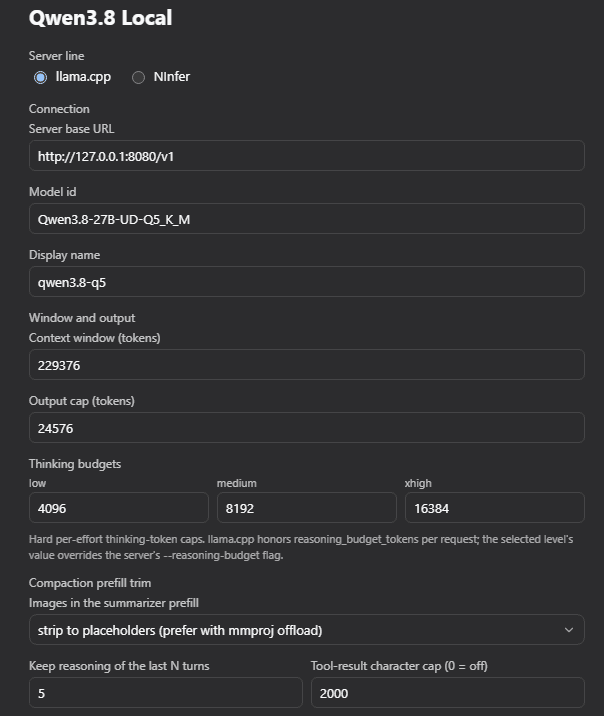
DSH settings → Qwen3.8 Local:
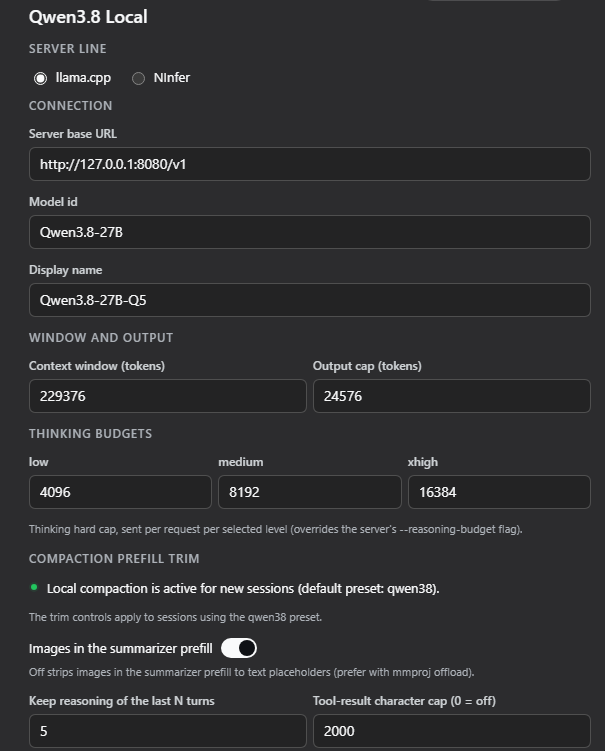
Per-line memory (connection, window numbers, budgets, trim knobs). The status dot is green when qwen38 is the default preset, amber when a different preset is the default, gray when the preset is missing. Changes apply live and persist to settings.yaml (hot-reloaded).
What can be tuned
The settings tab is the primary entry; headless profiles and patch/env accept the same fields (an id-scoped patch replaces the whole config; env covers what the patch does not set):
| Area | Fields (env vars) | Defaults |
|---|---|---|
| Server | baseURL, model, displayName, apiKey (DSH_QWEN38_BASE_URL / _MODEL / _DISPLAY_NAME / _API_KEY) |
http://localhost:8080/v1, qwen3.8-27b, same as model, none |
| Dialect | dialect (DSH_QWEN38_DIALECT) |
llamacpp (options: ninfer, tabbyapi) |
| Window | contextWindow, maxTokens (DSH_QWEN38_CONTEXT_WINDOW / _MAX_TOKENS) |
229376, 24576 |
| Thinking | thinkingBudgets (llamacpp + tabbyapi, per effort), defaultThinkingBudget (ninfer, headless/env only — the tab shows the startup flag), defaultEffort (DSH_QWEN38_DEFAULT_EFFORT) |
{ low: 4096, medium: 8192, xhigh: 16384 }, 16384, medium |
| Prefill trim | DSH_QWEN38_SUMMARIZE_IMAGES, DSH_QWEN38_SUMMARIZE_KEEP_TURNS, DSH_QWEN38_SUMMARIZE_TOOL_CHARS (env only) |
strip, 5, 2000 |
Limitations
- Flash-Next has a fast line and a compat line — the ExLlamaV3/TabbyAPI dialect (EXL3 quant, 256K context) is the fast path; the llama.cpp dialect still runs it at its own window/budget values.
- The TabbyAPI line's vision token count is not pinned — the token meter reports image capacity as unknown on that line until the ExLlamaV3 image-processor formula is measured (the request itself works; only the pre-flight capacity projection is affected).
- The preset seam is a web-surface feature — headless profiles do not mount
agent-presetsrows; the provider route (thinking budgets) works on both surfaces. - Summarizer internals depend on the engine version — the wire rules (thinking off, full output cap) hold for every engine version; engine internals are outside the plugin's control.
Update
dsh plugin --profile web update dsh-qwen38-local-qol
github: dependencies resolve to an exact commit — if the profile lockfile still pins the commit first installed, remove and re-add the plugin to force re-resolution. Updates never touch the generated preset or the settings section.
Uninstall
dsh plugin --profile web remove dsh-qwen38-local-qol- Delete the
qwen38preset on the Agent presets page. - Drop
agent-presets: { default: qwen38 }from~/.dsh/settings.yaml. - Restart DSH.
Session history, transcripts, model lines and engines are not state the plugin owns.
Develop
pnpm install
pnpm test
pnpm run build:client   # rebuild lib/client.js after touching src/client*
Host half = plain ESM JavaScript with JSDoc; the browser half is built by scripts/build-client.mjs and shipped as the committed lib/client.js. Design details: DESIGN.md.
License
中文
给本地跑 Qwen3.8 的人用的 DeepSeek Harness(DSH)QoL 插件(llama.cpp llama-server、NInfer 或 TabbyAPI——ExLlamaV3 后端服务器;均提供 OpenAI 兼容 /v1 API;配置层面兼容 Qwen3.8-Flash-Next)。零核心补丁、零 pi-ai 补丁文件。
安装
dsh plugin --profile web add github:Yunado/dsh-qwen38-local-qol
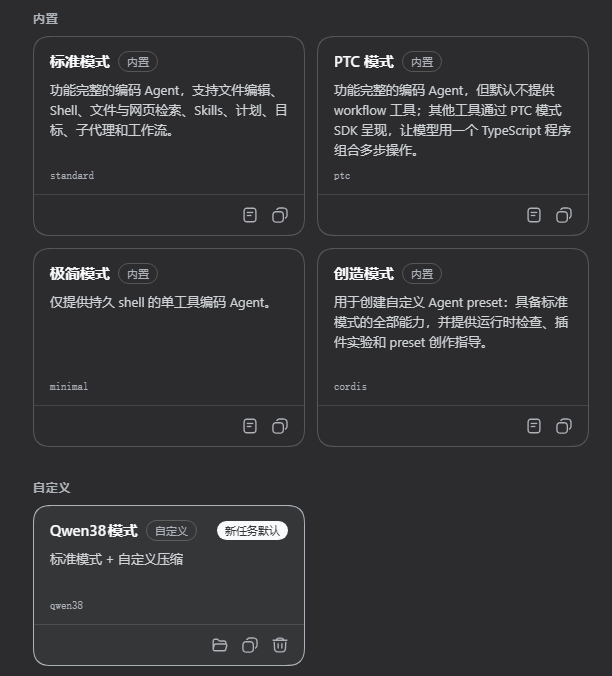
重启 dsh web:启动时插件从 standard preset 的组成生成 qwen38 用户 preset,且未配置默认时将其设为默认 agent preset。新会话自动使用;已有会话保留创建时的 preset。
功能特性
- 逐请求 thinking 预算。 llama.cpp 线每请求发送所选 effort 的预算(
reasoning_effort+reasoning_budget_tokens——覆盖服务端--reasoning-budget);NInfer 引擎的 thinking 预算由服务端启动参数(--default-thinking-budget)决定——设置 tab 在 NInfer 线只显示说明(无输入),defaultThinkingBudget字段保留为 headless/env 配置项;TabbyAPI 线两者都原生接受,逐请求按档发送。 - 压缩(compaction)后端。 摘要 prefill 先裁剪(只留近 N 轮 reasoning、图片降为文本占位符、工具结果按字数帽截断),且压缩调用强制 thinking off + 该线完整输出帽——checkpoint 不再被 token 帽截断。
- 设置 tab:图形化配置各线,即时生效。
设置 tab
DSH 设置 → Qwen3.8 本地:
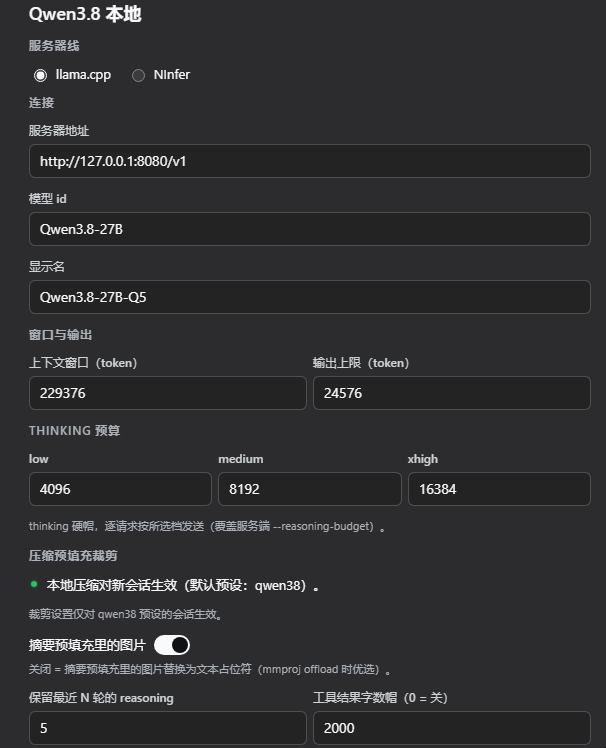
按线记忆(连接、窗口数字、预算、裁剪旋钮)。状态圆点:绿 = qwen38 是默认 preset,黄 = 默认是别的 preset,灰 = preset 缺失。改动即时生效并持久化到 settings.yaml(热加载)。
可调项
设置 tab 是主入口;headless profile 或补丁/环境接受同样字段(按 id 定向的补丁替换整个 config,环境回退只覆盖补丁没写的字段):
| 区域 | 字段(环境变量) | 默认 |
|---|---|---|
| 服务器 | baseURL、model、displayName、apiKey(DSH_QWEN38_BASE_URL / _MODEL / _DISPLAY_NAME / _API_KEY) |
http://localhost:8080/v1、qwen3.8-27b、同 model、无 |
| 方言 | dialect(DSH_QWEN38_DIALECT) |
llamacpp(可选:ninfer、tabbyapi) |
| 窗口 | contextWindow、maxTokens(DSH_QWEN38_CONTEXT_WINDOW / _MAX_TOKENS) |
229376、24576 |
| Thinking | thinkingBudgets(llamacpp + tabbyapi,按 effort)、defaultThinkingBudget(ninfer,仅 headless/env——tab 显示启动参数)、defaultEffort(DSH_QWEN38_DEFAULT_EFFORT) |
{ low: 4096, medium: 8192, xhigh: 16384 }、16384、medium |
| Prefill 裁剪 | DSH_QWEN38_SUMMARIZE_IMAGES、DSH_QWEN38_SUMMARIZE_KEEP_TURNS、DSH_QWEN38_SUMMARIZE_TOOL_CHARS(仅环境变量) |
strip、5、2000 |
已知限制
- Flash-Next 有快线与兼容线——ExLlamaV3/TabbyAPI 方言(EXL3 量化、256K 上下文)是快线;llama.cpp 方言仍可按自己的窗口/预算值跑它。
- TabbyAPI 线的视觉 token 数未钉——该线上 token meter 报图片容量未知,直到测出 ExLlamaV3 图像处理器公式(请求本身正常,只影响预检容量投影)。
- preset 接缝是 web 面功能——headless profile 不挂
agent-presets行;provider 路由(thinking 预算)两面都工作。 - 摘要器内部行为依赖引擎版本——wire 层规则(thinking off、完整输出帽)对所有引擎版本生效;引擎内部行为不在本插件控制之内。
更新
dsh plugin --profile web update dsh-qwen38-local-qol
github: 依赖按精确 commit 解析——若 profile 锁文件仍钉在首次安装时的 commit,remove 后重新 add 插件即可强制重新解析。更新不触碰生成的 preset 与设置节。
卸载
dsh plugin --profile web remove dsh-qwen38-local-qol- 在 Agent 预设页删除
qwen38preset。 ~/.dsh/settings.yaml删掉agent-presets: { default: qwen38 }。- 重启 DSH。
会话历史、transcript、模型线、引擎都不是插件持有的状态。
开发
pnpm install
pnpm test
pnpm run build:client   # 改完 src/client* 后重建 lib/client.js
宿主半边 = 带 JSDoc 的裸 ESM JavaScript;浏览器半边由 scripts/build-client.mjs 构建并以已提交的 lib/client.js 出货。设计细节:DESIGN.md。
许可
Related相关推荐
-
 liangmianya/dsh-synapse
A visual, non-linear conversation workspace plugin for DeepSeek Harness ; A canvas-based session explorer and branching …
-
 alaliqing/claude-paper
📖 Cross-agent research paper toolkit for Claude Code, Codex, OpenCode, and DeepSeek Harness—quick summaries, deep study…
-
 omdsh-dev/dsh-annotation
DSH Web 选中批注插件:选文字→批注→回车随消息发送;气泡隐藏批注块(零闪烁);回复按 Annotation N 逐条对照(可悬浮芯片)。官方 bundle,零核心改动
-
 Anionex/dsh-turn-rewind
deepseek harness对话和代码状态回退插件 | DSH — rewind conversation and workspace state, powered by a persistent Change Ledger
-
 hanshenmesen/dsh-turn-delete
Delete one complete turn from a DeepSeek Harness session without deleting the session
-
 qkycir-123/dsh-run2skill
Automatically turn successful DeepSeek Harness sessions into reusable, reviewable Agent Skills.
-
 Tyan66666/billion-context-dsh
Model-driven context management (Active Context Pruning / ACP) for the DeepSeek Harness — the model decides when and wha…
-
 PKUfudawei/dsh-capability-menu
Unified capability menu for DeepSeek Harness: manage exposure level (context footprint) and execution mode of MCP tools …