dylan121322/llm-adaptive
Project Overview项目介绍
llm-adaptive is a routing plugin for DeepSeek Harness that adds an adaptive provider. A flash classifier scores every request as low, medium, high, or critical, then the plugin walks the matching chain from pool.json to the first available backend. Use it to auto-pick model tier per request across a multi-model pool without manual switching. Pool edits apply on the next request. Caveat: a 120s decision cache and sticky mid-task protection can keep earlier levels active when the topic hasn't drifted.
llm-adaptive 是 DeepSeek Harness 的自适应模型路由插件,新增 adaptive 提供商。它通过 deepseek-v4-flash 分类器将每条请求按复杂度分为低/中/高/关键四级,再按 pool.json 中的链式配置路由到对应后端。适用于多模型环境下希望按任务难度自动调度、降低成本与延迟的场景。配置热更新,分类失败安全降级为 medium;注意 120 秒决策缓存可能使同主题的早/晚期请求共用旧分级。
请帮我了解并安装插件:【llm-adaptive】【https://github.com/dylan121322/llm-adaptive】Send this message to DSH in your current session. CLI install commands may not be accurate across systems — DSH will figure it out for you.把上面这条消息直接发给当前会话里的 DSH,让它帮你了解并安装。安装命令不一定准确,发给 DSH 更稳。
Or use CLI install (for developers)或使用命令行安装(适合开发者)
CLI Install命令行安装
dsh plugin add llm-adaptive把 dylan121322/llm-adaptive 加入你的 DSH 配置(web profile)即可启用。
READMEREADME
llm-adaptive

Adaptive model routing plugin for DeepSeek Harness. Adds an adaptive provider to the model picker: every LLM request is classified by a flash classifier (low / medium / high / critical) and routed to the matching backend provider through config-driven chains.
Features
- Per-request complexity classification —
deepseek-v4-flashcalled directly (never through a proxy, no recursion). - Context-aware judging — injects a rolling session-goal summary plus the recent turns into the classifier prompt (continuation / wrap-up / error-loop rules).
- Sticky level protection — a mid-task downgrade is held at the previous level unless the message carries explicit downgrade or wrap-up signals.
- Config-driven routing chains — chains come from
pool.json→routing.levels($activeexpands to the active provider, missing entries fall back to defaults); transport failures walk down the chain. - Classifier config from the pool — URL / model / key reference read from the
classifiersection ofpool.json(no hardcoded credentials). - Fail-open — any classification failure degrades to
medium; never blocks a request. - Observable — every decision (level, cause: llm/sticky/cache) is written to the plugin log.
- 120s decision cache — keyed by user-text head plus goal fingerprint.
Requirements
- DeepSeek Harness (dsh)
- A model pool file at
~/.dsh/tools/cc-switch-sync/pool.jsonwith:classifiersection:url,model,key_ref(resolved against~/.dsh/.credentials.yaml, poolapi_keyas fallback)routing.levels:low/medium/high/criticalchains
- A DeepSeek API key for the classifier
The pool file is produced by the cc-switch-sync import tool (or can be authored by hand). The plugin reads it on every request, so pool edits take effect immediately.
Install
dsh plugin add llm-adaptive
or, from a local checkout:
cd ~/.dsh/profiles/web && npx pnpm@10 install # with "llm-adaptive": "file:plugins/llm-adaptive"
Restart the dsh web service, then select adaptive(自动路由) in the /model picker.
Usage
- Open
/modeland chooseadaptive(自动路由). - Every subsequent LLM request is classified (low/medium/high/critical) and routed to the first available provider of that level's chain.
- Decisions are logged with
level=… cause=… chain=…to~/.dsh/hooks/plugin.log.
The explicit level models (low, medium, high, critical) are also listed in the picker for direct selection.
How it works
A custom LlmAdapter for the adaptive provider: stream() awaits classification (async generator), then forwards to the target backend via ctx.llm.prepareCall + stream (unified chunk protocol, passthrough). Request-level interception was chosen over proxy or request-layer hooks because dsh hot-swaps configuration and the prepared-call contract requires matching provider/model options.
License
MIT
Related相关推荐
- Pheobe-Southwood/dsh-acp-paseo dsh (DeepSeek Harness) ⇄ Paseo ACP integration bundle: auto-discovered model catalog, plan/execute modes, thinking level…
- Nagi-ovo/voyager Enhancement suite for Gemini, AI Studio, Claude & ChatGPT — plus a prompt manager for any websites, DeepSeek Harness inc…
-
 crafter-station/petdex
A public gallery of animated pets for Codex, Claude Code, DeepSeek Harness, Hermes, OpenCode, Gemini CLI, and more.
-
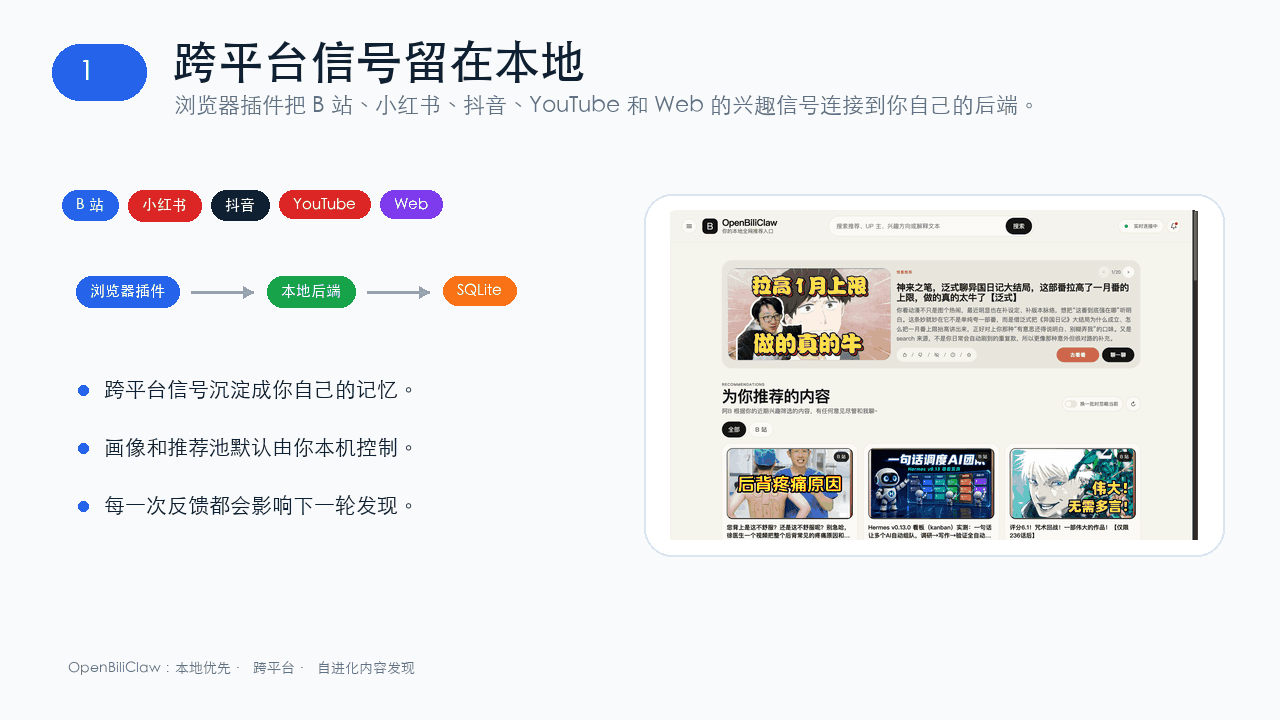 whiteguo233/OpenBiliClaw
本地私有、开源的自进化跨平台 AI 内容发现 Agent:先理解你,再主动从 B站、小红书、抖音、YouTube、X、知乎、Reddit、微博等平台与开放 Web 寻找内容。(支持 deepseek harness 插件) | Local-…
-
 edison7009/EchoBird
One-click install + model switch:Claude Code,Codex CLI (OpenAI), Grok Build (xAI), DeepSeek Harness, Kimi Code (Moonshot…
-
 V1ki/dsh-plugin-subscriptions
Use ChatGPT (Codex), Claude, and Grok (X Premium) subscriptions as DeepSeek Harness LLM providers — OAuth login in the w…
-
 Nwflower/dsh-chat-import
Import 14+ external agent chat histories (Claude Code, Codex, ChatGPT, Cursor, Gemini, Reasonix, opencode, ZCode, Grok B…
-
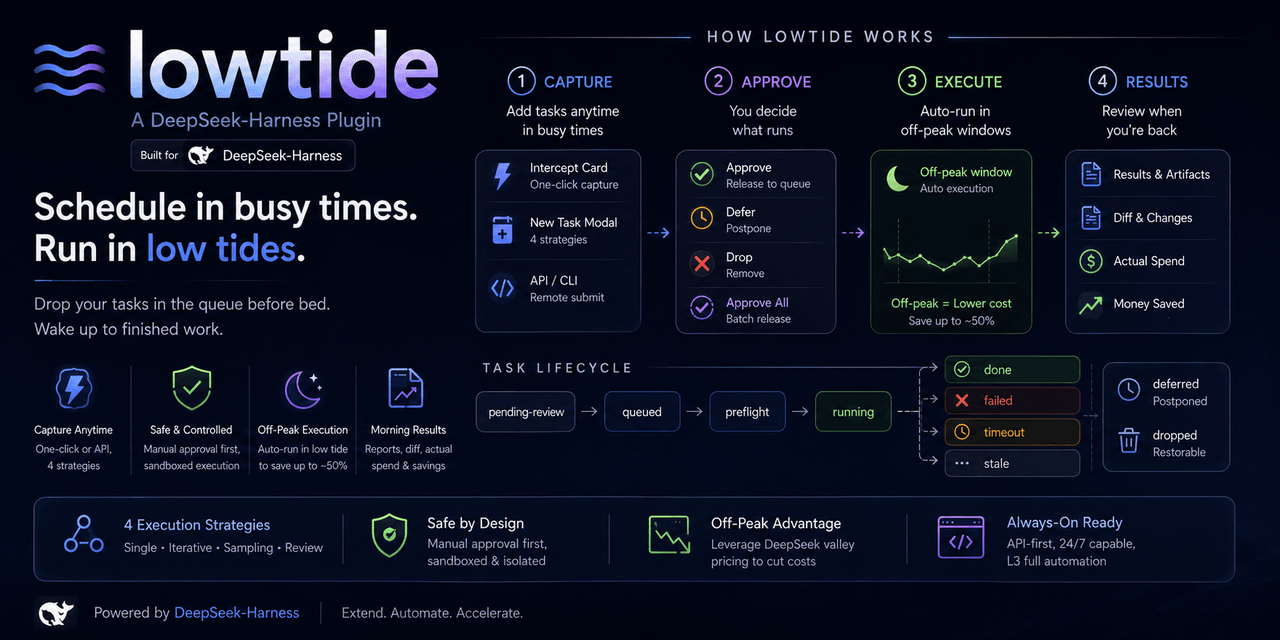 KelaoHu/dsh-lowtide
Time-shifting task delegation for DeepSeek Harness (dsh): plan tasks at leisure, they run unattended off-peak, come back…