xxww0098/dsh-plugin-oauth-subs
ChatGPT Codex and xAI Grok subscription OAuth for DeepSeek Harness — PKCE / device-code, local Responses proxy, llm-pi-ai sync
Project Overview项目介绍
This is an OAuth subscription plugin for DeepSeek Harness. It supports connecting official LLM subscriptions including ChatGPT, Grok, Zhipu GLM and Cursor, with OAuth authentication, credential import and quota display. Use it to route third-party cloud LLMs in DSH. It does not support local Ollama instances.
这是DeepSeek Harness的OAuth订阅插件,可对接ChatGPT、Grok、GLM、Cursor等多个官方大模型订阅服务,支持官方OAuth认证、已有凭据导入和配额显示,用于在DSH中路由使用这些第三方订阅大模型,仅适用于云端订阅,不支持本地Ollama服务。
请帮我了解并安装插件:【dsh-plugin-oauth-subs】【https://github.com/xxww0098/dsh-plugin-oauth-subs】Send this message to DSH in your current session. CLI install commands may not be accurate across systems — DSH will figure it out for you.把上面这条消息直接发给当前会话里的 DSH,让它帮你了解并安装。安装命令不一定准确,发给 DSH 更稳。
Or use CLI install (for developers)或使用命令行安装(适合开发者)
CLI Install命令行安装
dsh plugin --profile web add https://github.com/xxww0098/dsh-plugin-oauth-subs把 xxww0098/dsh-plugin-oauth-subs 加入你的 DSH 配置(web profile)即可启用。
READMEREADME
dsh-plugin-oauth-subs
简体中文 | English

Use a ChatGPT / Codex, xAI Grok, Zhipu GLM, AWS Kiro, Google Antigravity, Cursor, Ollama Cloud, Kimi Code Plan, or GitHub Copilot subscription inside DeepSeek Harness. Official OAuth, plus Kiro API keys, Cursor CLI/IDE reuse, Ollama API keys (ollama.com Cloud, not localhost:11434), Kimi device-code / kimi-code.json, and GitHub Copilot device-code / hosts.json. Loopback proxy + llm-pi-ai route sync; each family picks one DSH api from openai-responses | openai-completions | anthropic-messages.
Install
dsh plugin --profile web add https://github.com/xxww0098/dsh-plugin-oauth-subs
dsh web
Open Settings → OAuth subs. One card per account (quota on every card; Ollama Cloud has no quota bars). About Installed re-reads the package.json this process loaded (not a module-load freeze). A leftover dsh web after a wrapper/pidfile restart still serves the old process until that PID is killed (pgrep -lf 'dsh web'). If profile node_modules is newer, About lists On disk and may add …#<tag> even when that file is already latest. Or pnpm dsh web --patch ./cordis.patch.yml (id: oauth-subs).
Families
| Provider | Auth | DSH api | Upstream hop |
|---|---|---|---|
| ChatGPT Codex | PKCE localhost:1455 (1457 fallback); paste-callback; app_EMoamEEZ73f0CkXaXp7hrann |
openai-responses |
chatgpt.com/backend-api/codex/responses |
| xAI Grok | Device-code (default); PKCE 127.0.0.1:56121; b1a00492-073a-47ea-816f-4c329264a828 |
openai-responses |
api.x.ai/v1/responses |
| GLM · Z.ai (global) | ZCode CLI poll provider: zai; mint id.secret; client_P8X5CMWmlaRO9gyO-KSqtg |
anthropic-messages |
api.z.ai/api/anthropic (Completions leftover …/coding/paas/v4) |
| GLM · BigModel (China) | Same CLI poll, provider: bigmodel; poll JWT is the bearer; client zcode |
anthropic-messages |
open.bigmodel.cn/api/anthropic (Completions leftover …/coding/paas/v4) |
| AWS Kiro | Social PKCE app.kiro.dev (3128…53153) / Builder ID / IdC / Entra / ksk_ |
openai-completions |
q.<region>.amazonaws.com GenerateAssistantResponse |
| Google Antigravity | Google OAuth localhost:51121; paste-callback; 1071006060591-…apps.googleusercontent.com |
openai-completions |
daily-cloudcode-pa.googleapis.com/v1internal:streamGenerateContent |
| Cursor | PKCE poll cursor.com/loginDeepControl; or Import local Cursor |
openai-completions |
Connect agentn.us.api5.cursor.sh AgentService/Run |
| Ollama Cloud | Paste API key / import OLLAMA_API_KEY |
openai-completions |
https://ollama.com/v1/chat/completions |
| Kimi Code Plan | Device-code (no PKCE); import ~/.kimi-code/credentials/kimi-code.json; optional KIMI_API_KEY |
openai-completions |
https://api.kimi.com/coding/v1/chat/completions |
| GitHub Copilot | Device-code (no PKCE); import ~/.config/github-copilot/hosts.json; optional GITHUB_TOKEN |
openai-completions |
https://api.githubcopilot.com/chat/completions (tid= session) |
| Path | Family | ||
| --- | --- | ||
~/.codex/auth.json |
Codex | ||
~/.grok/auth.json, ~/.hermes/auth.json |
Grok | ||
~/.zcode/v2/config.json (also older cli/config.json / config.json) |
GLM | ||
~/.kiro/credentials.json; credentials.json (kiro.rs CWD); ~/.aws/sso/cache/kiro-auth-token.json |
Kiro | ||
Settings paste: kami / JSON / CSV / Social refresh / ksk_… |
Kiro | ||
~/.gemini/antigravity-cli/antigravity-oauth-token; ~/.cli-proxy-api/antigravity-*.json |
Antigravity | ||
macOS Keychain cursor-access-token / cursor-refresh-token; IDE state.vscdb (current OS user only); CURSOR_ACCESS_TOKEN |
Cursor | ||
OLLAMA_API_KEY env (not ~/.ollama/id_ed25519.pub) |
Ollama Cloud | ||
~/.kimi-code/credentials/kimi-code.json; read-only ~/.kimi/credentials/kimi-code.json; KIMI_API_KEY |
Kimi | ||
~/.config/github-copilot/hosts.json; OpenCode ~/.local/share/opencode/auth.json; COPILOT_GITHUB_TOKEN / GITHUB_TOKEN / GH_TOKEN |
Copilot |
Tokens: <profile>/data/dsh-plugin-oauth-subs/auth.json (0600). Models: models.json beside it.
How it works
| Plane | Role |
|---|---|
| Settings | OAuth login / import / logout, then model sync |
| llm-pi-ai | DSH call plane; routes to the loopback proxy |
| Loopback | http://127.0.0.1:8318/{codex,grok}/v1/responses, /glm/v1/messages (Completions leftover /glm/v1/chat/completions until the next sync), /{kiro,antigravity,cursor,ollama,kimi,copilot}/v1/chat/completions |
| Upstream | Refreshed subscription bearer |
Not a second LLM adapter. After Settings closes, DSH still calls the loopback proxy. Bind is loopback-only; local credential is DSH_OAUTH_SUBS_API_KEY. GLM 150% Coding Plan boost is identity (ZCode Desktop UA), not a protocol claim. Stack and module tree: AGENTS.md. Reference hops (official CLI + community reverse): docs/oauth.md.
Cache
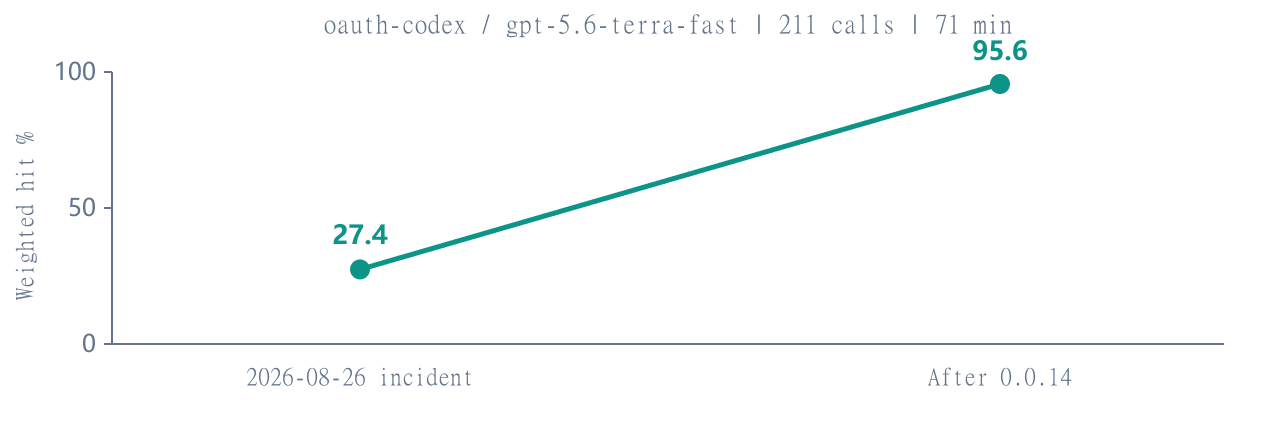
Acceptance on the full session-772f7f3a-… SkillStar turn (oauth-codex / gpt-5.6-terra-fast, 211 calls, 71 min):
| 2026-08-26 incident | After 0.0.14 affinity headers | |
|---|---|---|
| Weighted cache hit | 27.4% | 95.6% |
| Prefix reuse (median) | — | 99.6% |
| Affinity misses | 47 / 90 zero-cache | 0 |
| Prefix rewrites | — | 1 adapter rebuild + 9 compaction |
| TRANSPORT faults | 29 | 0 |
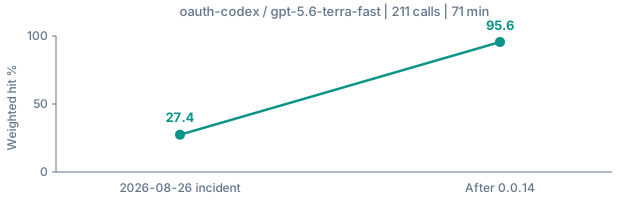
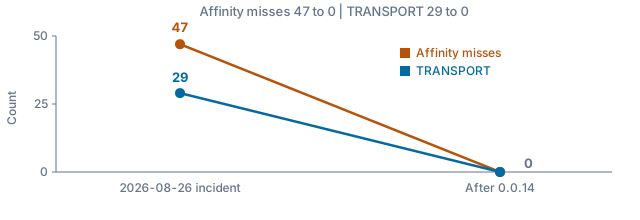
Remaining uncached tokens are almost all new tool output (delta) plus expected prefix rewrites: leaving plan mode (step 55, 169k) and DSH compaction (330k); the next call after each rewrite reused ~99%. Healthy: weighted hit ≥ 80%, zero affinity misses, no TRANSPORT. Compaction / request/header rebuild zeros do not fail the session. Details: docs/error.md.
Diagnose
npm run analyze -- path/to/session.jsonl
node --experimental-strip-types scripts/analyze-session.ts --json path/to/session.jsonl
node --experimental-strip-types scripts/analyze-session.ts --fail-below 80 path/to/session.jsonl
The analyzer labels each call cold_start / delta / compaction / rebuild / affinity_miss so a compacted session is not flagged as a shard regression. Import as dsh-plugin-oauth-subs/analyze-session.
Fast / models / reasoning
Login and chat use official client identity; UA / fingerprint live in each src/oauth/<id>/README.md. The repos those fingerprints were copied from are listed in docs/oauth.md. Settings → Models: per-family checkboxes (default all on except 900K). Reasoning is set in the Harness session menu, not Settings → Models. Fast and 900K spend quota faster.
| Family | Fast | Window | Thinking |
|---|---|---|---|
| Codex GPT-6 Astra / GPT-5.6 Sol / Terra / Luna | Yes. -fast → Priority (service_tier: "priority" + x-codex-routing-hint; store: false) |
258K default; -900k (872K) |
low / medium / high / xhigh / max |
| Other Codex | 5.4 / 5.5 Yes; Mini / Spark No (empty service_tiers; leftover *-fast peeled locally) |
GPT-5.4 -900k (1M) |
low–xhigh (no minimal) |
| Grok | No. 2026-08-30: 83.34 vs 82.80 tok/s (0.994). Older ids reject the field | — | 4.6: low / medium / high / xhigh (unset = high); 4.5: no xhigh |
| GLM | — | — | 5.3 / Flash: low / high / max (default max; no medium; disabled 400s). Turbo: on, no depth. Flash is the only GLM image row |
| Kiro | — | — | GPT-5.6: off / low / medium / high / xhigh / max (off → wire none). Opus 5 / 4.8 / 4.7 and Sonnet 5 add xhigh; 4.6 family to max; Haiku / OSS: none. Catalog: kiro.dev/docs/models (no Auto) |
| Ollama Cloud | No | Live GET /api/tags (static 20-row Cloud snapshot fallback). Context from POST /api/show model_info.<family>.context_length. No quota bars |
off / low / medium / high / max (off → wire none) |
| Kimi | No | Live GET /coding/v1/models (static kimi-for-coding / highspeed / k3, 256k/32k). Prefix-hash cache |
off / minimal / low / medium / high / xhigh / max → thinking.effort |
| Copilot | No | Live GET {api}/models (static GPT / Claude / Gemini / Grok floor). Prefix-hash + X-Interaction-Id |
live reasoning_effort when the catalog advertises it |
Codex Priority echo created=auto / completed=default is not a confirmation (openai/codex#14204). 2026-08-26 Luna: 88.3 vs 57.5 tok/s (1.54×); 2026-08-30 interleaved mean 1.33× (1.90 then 0.93). Throughput-only; TTFT and cache unchanged.
Quota
| Subscription | Endpoint | Display |
|---|---|---|
| ChatGPT Codex | chatgpt.com/backend-api/wham/usage |
Plan badge (Plus / Pro / Team …) plus 5-hour + weekly windows, remaining percent and reset time |
| ChatGPT Codex reset | …/wham/rate-limit-reset-credits + /consume |
Banked weekly-window reset credits and expiry; one confirm button per credit on the Codex card |
| xAI Grok | cli-chat-proxy.grok.com/v1/billing?format=credits plus /v1/user?include=subscription |
Plan badge (SuperGrok / X Premium+ …) plus period usage, prepaid balance, product split |
| Zhipu GLM | api.z.ai or open.bigmodel.cn monitor/usage/quota/limit |
Plan badge (Lite / Pro / Max) plus Coding Plan credit windows; host follows the active account |
| Google Antigravity | daily-cloudcode-pa loadCodeAssist + fetchAvailableModels (prod only on 5xx / transport) |
Plan badge (Pro / Ultra / Free / Standard) plus SkillStar model-group remaining bars and reset time |
| Cursor | api2.cursor.sh DashboardService/GetCurrentPeriodUsage |
Plan badge (Free / Pro / Pro+ / Ultra …) plus cycle remaining percent |
| Kimi Code | api.kimi.com/coding/v1/usages + /me |
Plan badge from /me.user_level_name plus remaining bars; no invented reset times |
| GitHub Copilot | api.github.com/copilot_internal/user |
Plan badge (Free / Pro / Pro+ / Business / Enterprise) plus Premium remaining percent |
Refresh about once a minute, or Refresh quota. Bars: hsl(remaining × 1.2, 78%, 38%). Codex pro → Pro 20x / $200, prolite → Pro 5x / $100. Plus/Pro may bank weekly resets — one confirm button per credit on the Codex card (Harness risk dialog, then POST …/consume with { redeem_request_id } + idempotencyKey). That spend refreshes the weekly window. Grok has no equivalent. Ollama Cloud has no documented quota JSON (/api/quota 404); the card stays idle with no bars.
Options
| Option | Default | Notes |
|---|---|---|
port |
8318 |
Loopback proxy port |
provider |
oauth |
llm-pi-ai route prefix (oauth-codex / oauth-grok / oauth-glm / oauth-antigravity) |
dataDir |
profile data dir | auth.json, models.json, and proxy-key |
grokLogin |
device |
device or pkce |
Develop
npm test
npm run analyze -- path/to/session.jsonl
See CONTRIBUTING.md.
Related相关推荐
- Nagi-ovo/voyager Enhancement suite for Gemini, AI Studio, Claude & ChatGPT — plus a prompt manager for any websites, DeepSeek Harness inc…
-
 crafter-station/petdex
A public gallery of animated pets for Codex, Claude Code, DeepSeek Harness, Hermes, OpenCode, Gemini CLI, and more.
-
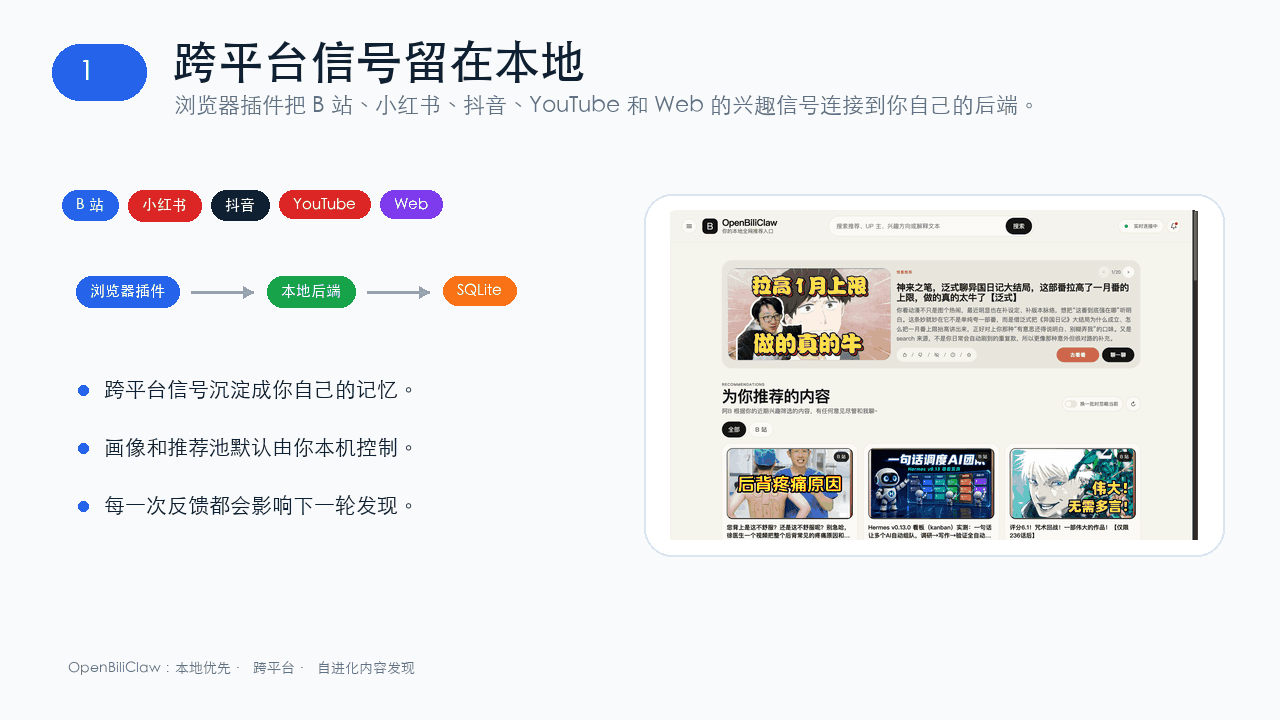 whiteguo233/OpenBiliClaw
本地私有、开源的自进化跨平台 AI 内容发现 Agent:先理解你,再主动从 B站、小红书、抖音、YouTube、X、知乎、Reddit、微博等平台与开放 Web 寻找内容。(支持 deepseek harness 插件) | Local-…
-
 edison7009/EchoBird
One-click install + model switch:Claude Code,Codex CLI (OpenAI), Grok Build (xAI), DeepSeek Harness, Kimi Code (Moonshot…
-
 V1ki/dsh-plugin-subscriptions
Use ChatGPT (Codex), Claude, and Grok (X Premium) subscriptions as DeepSeek Harness LLM providers — OAuth login in the w…
-
 Nwflower/dsh-chat-import
Import 14+ external agent chat histories (Claude Code, Codex, ChatGPT, Cursor, Gemini, Reasonix, opencode, ZCode, Grok B…
-
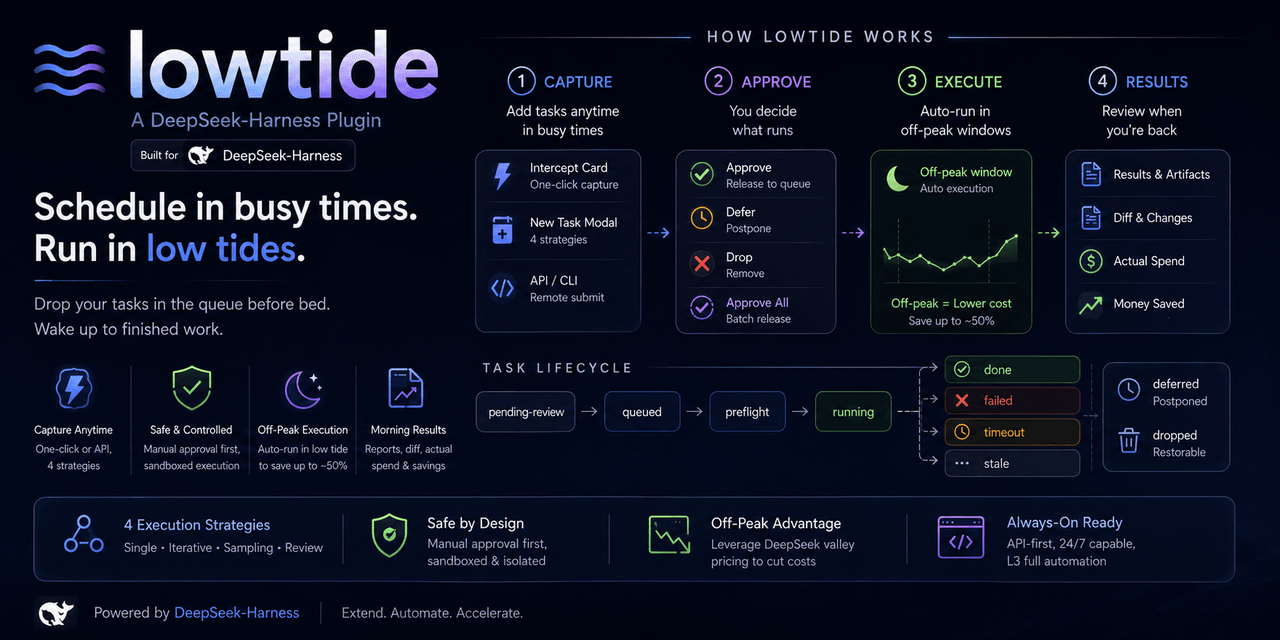 KelaoHu/dsh-lowtide
Time-shifting task delegation for DeepSeek Harness (dsh): plan tasks at leisure, they run unattended off-peak, come back…
-
 corrinehu/dsh-workbuddy-connect
将 WorkBuddy 桌面 App 包含的模型自动接入 DeepSeek Harness,零配置使用。Bring the models in the WorkBuddy desktop app into DeepSeek Harness …