tianji-qingtian/dsh-model-router
模型路由与成本优化器:针对DeepSeek Harness,简单问题由flash快速回答,故障自动降级,实时显示token/缓存/成本面板
Project Overview项目介绍
DSH Model Router routes light requests to a cheap model via a zero-prefix flash judge (SIMPLE/AGENTIC, one-word output) and sends heavy ones to the main model. SIMPLE hits trigger a built-in question prompt offering a quick answer or main-model path; image messages are steered to the catalog's image-capable model. Use /router auto|off or the route_model tool to toggle behavior. Transient RATE_LIMIT, SERVER, TIMEOUT, and EMPTY_RESPONSE errors degrade to the cheap model with one retry. A composer dock panel shows live miss/out, cache hit rate, estimated cost, and per-model usage. Caveat: auto/off state is durable, but the transient-failure degradation flag is process-local.
DSH 模型路由插件,通过零前缀 flash 判别(SIMPLE/AGENTIC,单词输出)将轻量请求路由至廉价模型,复杂请求走主模型。SIMPLE 命中会通过内置问询界面让用户选择快速回答或主模型回答;图片消息自动转交视觉模型;可手动 /router auto|off 或 route_model 工具控制;遇到 RATE_LIMIT、SERVER 等瞬时错误会降级到廉价模型重试一次;composer 下方的 dock 面板实时显示 miss/out、缓存命中率、估算成本与按模型统计。注意路由状态混合:auto/off 持久化,失败降级标志为进程局部。
请帮我了解并安装插件:【dsh-model-router】【https://github.com/tianji-qingtian/dsh-model-router】Send this message to DSH in your current session. CLI install commands may not be accurate across systems — DSH will figure it out for you.把上面这条消息直接发给当前会话里的 DSH,让它帮你了解并安装。安装命令不一定准确,发给 DSH 更稳。
Or use CLI install (for developers)或使用命令行安装(适合开发者)
CLI Install命令行安装
dsh plugin --profile web add "github:tianji-qingtian/dsh-model-router#v0.9.4"把 tianji-qingtian/dsh-model-router 加入你的 DSH 配置(web profile)即可启用。
READMEREADME
dsh-model-router
Model Router & Cost Optimizer for DeepSeek Harness (dsh). Answers simple questions directly on the cheap model (zero prefix, no cache tax), degrades gracefully on transient provider failures, and shows live per-session token / cache-hit / cost figures right under the composer.
The harness is in developer preview and iterates quickly — expect compatibility-breaking changes.
中文说明见 README.zh.md。
Features
- Cheap-model judge routing — clearly heavy work (strong keywords / long payloads) goes straight to the main model with zero added latency. Everything else is decided by a zero-prefix flash judge call (
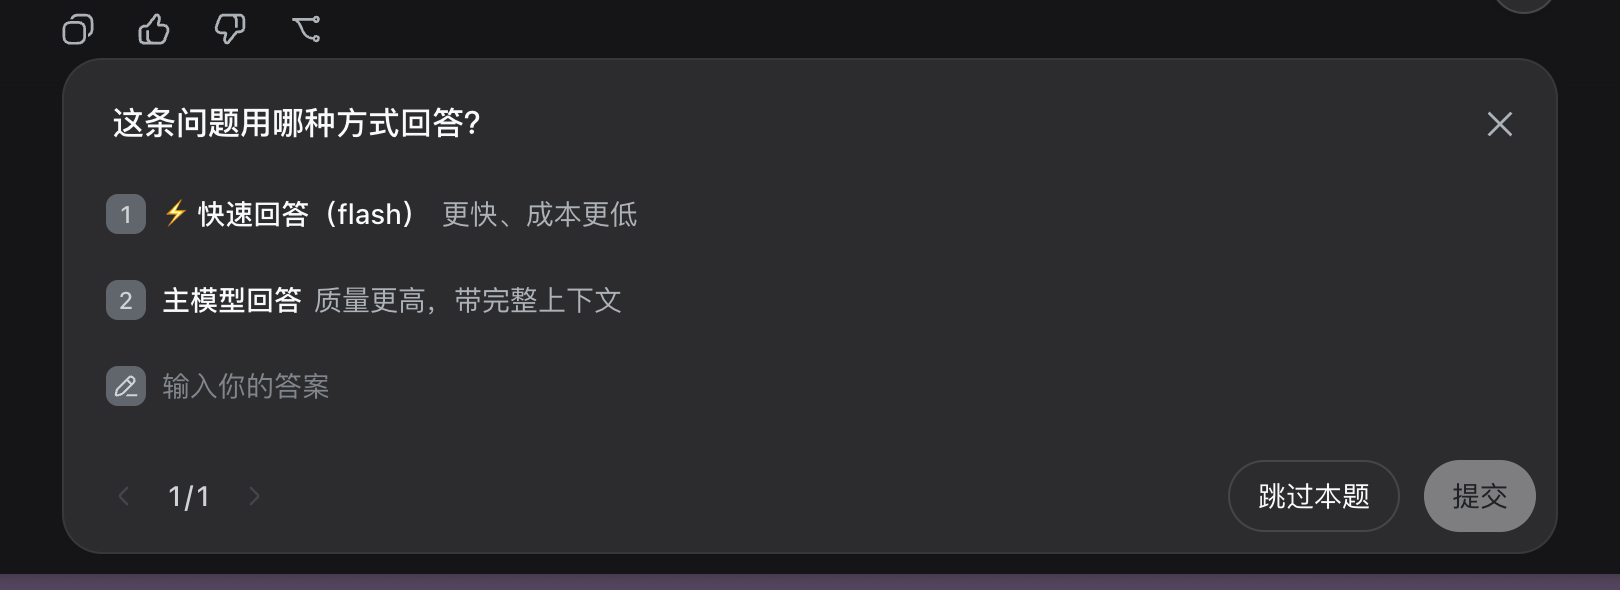
SIMPLE/AGENTIC, one word, 64-token cap, thinking off). The judge also sees the last assistant reply, so context-dependent follow-ups (它 / 这个 / 继续 …) are never misrouted to a context-free answer. - Ask before quick-answering — in auto mode, every SIMPLE hit asks the user through the built-in question UI: ⚡ 快速回答(flash) or 主模型回答. Choosing the main model (or dismissing the question) takes the normal flow; subagent sessions fall back automatically. The question text follows the request language.
- Direct quick-answer — when the user picks the quick option (or a quick answer is otherwise produced), the router rejects the step, runs a zero-prefix one-shot stream on the cheap model (no cache-miss tax), and writes the question + answer straight into the session log inside a step envelope — the user sees an ordinary Q&A exchange prefixed with a
⚡ 快速回答 / Quick answer · <model>marker (matched to the question language), the main model never runs for it, and no subagent sessions, relay cards, or toasts are created. The main session's model and prefix cache are never touched. - Vision-aware routing — messages carrying image blocks are routed to the catalog's image-capable model when one exists (e.g.
deepseek-v4-flash-vision-exp), including the quick-answer judge/stream; without an image-capable model they fall back to the main model instead of being answered blind on a text-only flash. - Model picker respected — the router never overrides the model chosen in the composer picker or via
selectModel, including relay/proxy providers (e.g.kabuai):agent/requestpasses the harness's requested config through unchanged, and quick answers always run on the session provider's own cheap model. (No drift healing — its original cause, a forgedrequest/header, was removed at the root in v0.9.2.) - Auto / off toggle — the dock panel and
/router auto|off(plus theroute_modeltool) simply enable or disable quick-answering for the session. There is no per-request model flipping to configure. - Automatic fallback — transient failures (
RATE_LIMIT,SERVER,TIMEOUT,EMPTY_RESPONSE) degrade the turn to the cheap model and retry once; anything else delegates to the provider's own retry policy. - Real usage metering — a session projection folds the durable log: real adapter token usage (input / output / cache read / cache write / reasoning), per-model breakdown, and estimated cost from a model-class price table. Projection-based, so the numbers are replay-safe and survive cold sessions.
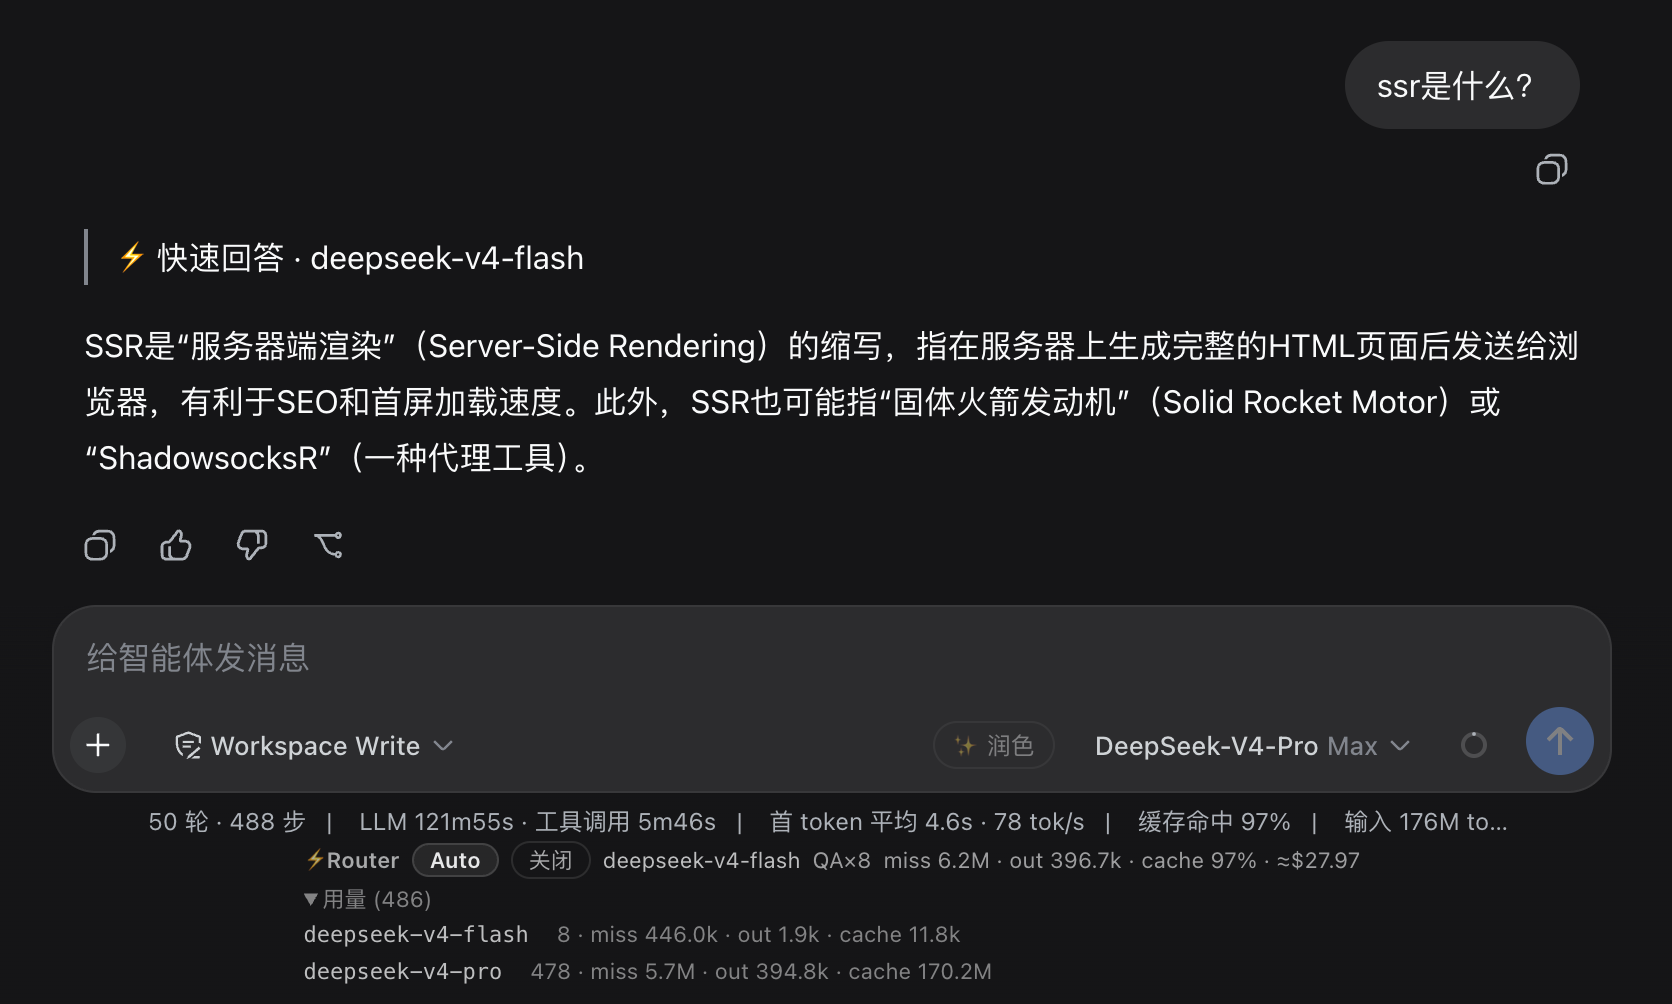
- Composer dock panel (i18n zh/en) — Auto / 关闭 toggle, current model,
miss/out/cache%/≈$line, aQA×Nquick-answer counter (with a brief inline highlight on each direct answer), and a per-model usage breakdown. Reactively driven byuseProjection; the toggle reuses the built-incommandsremote — no custom wire protocol. UI strings are localized through the harnesslocaleservice.
Screenshots
Quick answers land as ordinary chat messages with a ⚡ 快速回答 / Quick answer marker:
The router dock under the composer — Auto / 关闭 toggle, current model, live token / cache-hit / cost figures, and the per-model usage breakdown:
Install
Prerequisites
The dsh CLI must be on your PATH. If you only ever ran the harness through npx, dsh is not installed and you will get zsh: command not found: dsh — install it globally first (harness 0.1.1-rc.2 or newer is required):
npm install -g @deepseek-ai/dsh
pnpm add -g @deepseek-ai/dsh also works if your pnpm global bin dir is on PATH (otherwise pnpm asks you to run pnpm setup first). Alternatively skip the global install and prefix the commands below with npx @deepseek-ai/dsh ….
Add the bundle
# 1. add the bundle to your web profile (pnpm-backed; the built lib/ artifacts
#    are committed in this repo, so no build script runs at install time).
#    Prefer a release tag (#v0.9.4); #main tracks the latest commit.
dsh plugin --profile web add "github:tianji-qingtian/dsh-model-router#v0.9.4"

# 2. restart the harness with that profile — `add` only edits the profile
#    files; a running instance does not hot-load the new bundle
dsh --profile web
After the restart the ⚡Router panel appears under the composer in the Web UI, and the /router command plus the route_model tool are registered once the host half loads. Verify under Settings → Plugins that dsh-model-router is listed.
A dynamic (session-only) prototype with the same name may already be running inside one session; it is unrelated to the installed bundle and disappears with the harness process.
How it works
| Piece | Mechanism |
|---|---|
| Step classification | agent/pre-step waterfall — strong-keyword fast path, then a zero-prefix flash judge call (SIMPLE / AGENTIC) with the last assistant reply for reference detection |
| Quick answers | agent/pre-step rejects the step after a zero-prefix llm.stream on the cheap model; the question + answer are appended to the session log (user/message + a forged step/start…assistant/message…step/end envelope) — the main model never runs |
| Model picker / relay | agent/request passes the harness's requested config through unchanged — the composer picker, selectModel, and relay providers (e.g. kabuai) all work mid-session |
| Failure fallback | agent/request-error waterfall — returns { kind: 'retry' } after flagging the turn; the retry re-enters agent/request and lands on the cheap model |
| Stats | sessionProjections.register('modelRouter', …) folded over request/header (current/changes only), command/run, and assistant/message events — usage is attributed via each message's own source.model |
| Dock UI | conversation.composer.dock slot + standard useProjection prop + locale service for zh/en text |
| Manual control | `/router auto |
The cheap/strong model pair is discovered at runtime from the provider's catalog (llm.listModels): ids matching flash|chat|mini|turbo|haiku|lite|air|nano are cheap candidates, pro|reasoner|opus|sonnet|max|ultra|premium|r1 are strong. With the stock DeepSeek adapter that is deepseek-v4-flash ↔ deepseek-v4-pro.
Cost estimates
The price table is a model-class estimate (USD per 1M tokens) living at the top of src/index.js:
const PRICE_TABLE = [
  { test: CHEAP_RE, input: 0.27, output: 1.10, cacheHit: 0.07 },
  { test: STRONG_RE, input: 0.55, output: 2.19, cacheHit: 0.14 },
]
Edit it to match your account's actual pricing; the panel always labels the number with ≈. Cache hits are billed at the cache-hit price, not the input price.
Counting semantics: harness TokenUsage fields are disjoint — inputTokens already excludes cache reads (DeepSeek reports prompt_tokens = hit + miss; the adapter subtracts hits out). The panel therefore shows miss … · cache N% where the hit rate is hit / (hit + miss); a healthy long conversation typically sits in the high 90s.
Known limitations
- Routing state is split: the auto/off mode is durable (folded by the projection from the session's
command/runevents, so it survives restarts), while the transient-failure degradation flag is process-local and resets with the harness. useProjection-driven stats reflect the whole session log — history recorded before installation is included, which is intentional.- Direct quick answers write a forged step envelope into the session log (usage is attributed from the message's own
source.model; no fakerequest/headeris written since v0.9.2 — it would persist across restarts and mis-attribute the first real call after resume). This satisfies the current session invariants (the step is appended before the real step starts), but it is the most harness-coupled part of the plugin — worth re-checking after harness upgrades.
License
MIT
Related相关推荐
-
 songoao25/dsh-bottom-info-bar
Bottom Info Bar — an information bar plugin for DeepSeek Harness: provider/model, live balance, peak/off-peak pricing wi…
- YZz-S/dsh-token-cost-meter Community plugins for DeepSeek Harness (DSH) Web GUI: session token cost meter with official dynamic pricing, DeepSeek &…
-
 Jannchie/dsh-bill
DSH (DeepSeek Harness) plugin: per-session cost line + cost attribution report, priced by llm-pricing
-
 jiay98528-dev/dsh-model-sync
Writes live provider model lists into DSH settings. Composer rings show 5h/7d plan windows or metered balance for the cu…
- bjzkhy/dsh-token-ledger-pro DSH cost panel: meters every request from session events, prices it against a built-in catalog of 136 models across 16 p…
- GeekRicardo/dsh-balance DeepSeek Harness web 插件:输入框下方状态栏展示当前供应商的余额/用量 —— DeepSeek 官方余额 + 本会话花费,Kimi Coding、OpenCode Go、GLM Coding Plan 等订阅用量(支持的…
-
 AnLifeX/dsh-credits
DeepSeek Harness(dsh web)额度插件:跟随当前模型显示官方余额或 OpenCode Go 订阅用量,支持本会话估算、跨会话累计消耗与可视化设置。
-
 Han-1413141/dsh-cost-meter
DeepSeek Harness session cost meter plugin: session/daily cost, budget, history, OpenCode Go quota, official & custom-pr…