vibe-any/dsh-plugin-save-token
A DeepSeek Harness (dsh) dynamic plugin that cuts token cost without cutting model intelligence
Project Overview项目介绍
DSH dynamic plugin save-token reduces token cost at the model-request entry point without sacrificing model intelligence. It applies structure-aware slimming: pipe-delimited tables get stride-sampled with line numbers, uniform JSON arrays are re-encoded losslessly in TOON tabular form, and error lines in logs are preserved. Original text is always spilled to disk with a save_token_expand retrieval path, so any replacement stays one-step reversible. Byte-identical outputs within 90s are deduplicated; only results passing both a 72% byte cap and a strict token-decrease estimate are adopted, and pressure above 120k tokens triggers dsh's native compaction. Designed for long agent sessions, large API responses, and CLI debugging. Caveat: read tool output is exempt by design.
DSH 动态插件 save-token,用于在不损伤模型智能的前提下削减 token 成本。它在每次请求进入时对超大工具输出做结构感知压缩:管道表格做步长采样并保留行号、均匀 JSON 数组先走 TOON 无损转表、错误日志强制保留 error 行;原文始终落盘并暴露 save_token_expand 一键取回。当输出在 90 秒窗口内字节重复时自动去重,估算 token 严格下降且压缩后字节≤72% 时才生效,否则原样透传,并在上下文超 120k 时触发 dsh 原生 compaction。适合长会话、批量 API 与 CLI 排障;唯一注意:read 工具输出按设计被豁免,不会被压缩。
请帮我了解并安装插件:【dsh-plugin-save-token】【https://github.com/vibe-any/dsh-plugin-save-token】Send this message to DSH in your current session. CLI install commands may not be accurate across systems — DSH will figure it out for you.把上面这条消息直接发给当前会话里的 DSH,让它帮你了解并安装。安装命令不一定准确,发给 DSH 更稳。
Or use CLI install (for developers)或使用命令行安装(适合开发者)
CLI Install命令行安装
dsh plugin --profile web add dsh-plugin-save-token把 vibe-any/dsh-plugin-save-token 加入你的 DSH 配置(web profile)即可启用。
READMEREADME
dsh-plugin-save-token
English | 简体中文
In one sentence: a DeepSeek Harness (dsh) dynamic plugin that cuts token cost without cutting model intelligence.
Codex user? The same token-optimization brain ships as a standard Codex CLI plugin (MCP stdio server) in
codex-plugin-save-token/— see its README.
It slims down oversized tool outputs at the entrance of every model request — reversibly and structure-aware. The full original text is always saved to disk; what the model sees is always a condensed version carrying a retrieval path. Every optimization obeys one red line: any replacement must be restorable in one step, and the estimated token count after compression must be strictly smaller than the original.
Why you need it
- The bulk of agentic-session cost is tool output that keeps re-entering the context: large JSON from APIs, CLI tables, logs. The same 40KB price table may be billed again on every conversation turn.
- But blunt truncation degrades intelligence: research shows that even with perfect retrieval, merely padding the context with irrelevant content drops accuracy by 13.9–85% (curated in "Context Length Alone Hurts"); conversely, over-compression fails too — in production randomized controlled trials, aggressive compression (keep ratio 0.2) actually made cost +1.8% worse, while moderate compression (0.5) delivered −27.9%.
- Conclusion: the right way to save tokens is structure-preserving slimming, not content hacking. All strategies in this plugin are designed within that boundary.
Core optimizations
1. Structure-aware compression: no more blind table slicing
Detects pipe-delimited high-density table rows (≥70% of lines sharing the same separator profile). When matched, instead of a blind head/tail window it does: keep the first 60 rows verbatim + stride-sample the middle section every N rows with original line numbers annotated (L61: ...) + keep the last 40 rows verbatim. The model receives a "map with coordinates" — any segment can be fetched precisely by line number.
Reference: rtk's never-worse guard and error-line retention policy; the stride sampling is this plugin's improvement over rtk's head/tail window.
2. TOON-style lossless encoding first
Uniform JSON arrays (e.g. API responses with 300 homogeneous objects) first go through deterministic tabular re-encoding: prices[300]{model,input,output}: — one schema header line + CSV data rows. Keys are written once, zero information loss, and the notice explicitly says "zero information loss". Lossy paths are only used when the lossless route is unavailable.
Reference: TOON — Token-Oriented Object Notation; measured savings of 30–60% tokens on uniform arrays.
3. Compress means spill (CCR): never burn the bridge
Before every replacement, the original text is written to disk via the dsh spillStore; the replacement embeds two retrieval paths: the dynamic tool save_token_expand (one-call fetch by marker id) plus a file locator for the original (readable directly with read/grep). If spilling fails, compression is abandoned — reversibility is a hard precondition, not an option.
Reference: headroom's CCR (Compress-Cache-Retrieve) pattern.
4. Cross-turn dedup
Tool-call results byte-identical within a 90-second window (rerunning the same command, etc.) are replaced by one stub: "This output is identical to N seconds ago, refer to earlier context." Prevents the same large output from appearing twice in the context.
Reference: headroom's cross-turn dedup.
5. Never-worse double gate
A candidate compressed result is adopted only if it passes both gates:
- Byte gate: compressed ≤ 72% of the original (
keepRatioMax=0.72, more conservative than the RCT-validated 0.5), and absolute savings ≥500B; - Token gate: estimated tokens must strictly decrease (an llmtrim-style quality-gating idea). If either gate fails, the output passes through untouched.
Reference: RCT boundary data and quality-gating survey in awesome-llm-token-optimization.
6. Error-line protection
Within the omitted region of log-like output, up to 25 lines matching error/fatal/traceback/timeout... are kept (with line-number prefixes). Debugging evidence is never compressed away.
Reference: rtk's error-line keeps.
7. Compaction pressure coupling
At each reasoning-step boundary, check the session's most recent actual context size; above 120k tokens (10-minute cooldown), fire dsh's native compaction.compactIfNeeded() with 'pressure' and let the engine decide when to summarize history.
The threshold is a conservative water line (sized for 128k-class context windows); compaction itself is built into dsh — the plugin only hands over the trigger at the right moment.
8. Full-chain metering + dual-panel dashboard
Every llm/stream is intercepted: real billed tokens (input/cached/output/reasoning) and "tokens avoided from context" are accounted separately. Historical messages are scanned for [save-token #id] markers to total savings (including multi-turn replays). The Settings page hosts a full panel (KPIs, per-request stacked chart, top-tools leaderboard, activity feed), plus a persistent live strip under the input box.
Measured results
End-to-end A/B on real agent tasks (2026-08-29)
Randomized comparison on GAIA / Terminal-Bench / SWE-bench-Verified tasks — unique variable: the plugin's compress/dedupe switches; both arms under identical constraints that force large tool output to be printed directly into the conversation. Full data, scripts and per-episode records: bench/, report: bench/report_2026-08-29.md.
| Episodes | Success rate | Total tokens | Compressions | Per-episode median |
|---|---|---|---|---|
| 24/24 (6 tasks × 2 arms × n=2) | 100% vs 100% | 5.25M vs 4.32M (−17.6%) | 16 events across 8/12 episodes | −56% |
Take-aways: the plugin pays off exactly when large tool output lands directly in the context (verbose test runs, raw log/JSON dumps); when agents go through the write-file-then-read pattern it never triggers — and costs nothing. Success rate was never hurt.
End-to-end A/B, round 2 — the optimized build (2026-09-03, v2.4.1)
Same harness re-run after the v2.4.1 optimizations (lossless-TOON-first pipeline,
gated fallback, cache-aware layer), this time on a Linux host. 24/24 valid
episodes again; unique variable unchanged. Report: bench/report_2026-09-03.md, records: bench/results/raw2/, summary: bench/results/summary-r2.md.
| Metric | baseline | treatment (v2.4.1 on) |
|---|---|---|
| Success rate | 100% (12/12) | 100% (12/12) — 48/48 across both rounds, zero damage re-confirmed |
| Provider cache-hit rate | 90.0% | 90.7% — held at 91.1% even in the heaviest episode (1.86M tokens of repeated dump/expand cycles) |
| Tokens avoided (plugin estimate) | — | ~560k — 11 compressions across 6/12 episodes (13.8% of their tokens) |
| SWE long-context tasks (sympy / django) | — | −19.7% / −18.0%, both repeats same direction |
Take-aways: on the optimized build the value proposition sharpens — savings concentrate exactly where context is longest and output is largest (SWE-style agent runs), the cache-aware marker-replay layer keeps provider cache hits stable even under worst-case repeated re-reading, and success rate remains untouched. As with any n=2 study, one agent-side strategy outlier can outweigh per-output savings in the aggregate — see the report's paired per-task analysis for the breakdown.
Single-event compression strength
| Input | Before | After | Strategy |
|---|---|---|---|
| CLI price table (400-line pipe table) | 41,727 B | 15,191 B (−64%) | Structure-aware: verbatim head/tail + stride-sampled middle with original line numbers |
| Model-price JSON registry (300-item uniform array) | 34,000 B | 19,935 B (−41%) | TOON lossless route, zero information loss |
Anti-pattern on record: an early version once applied blind head/tail windowing to a 35.5KB LiteLLM price registry; subagents couldn't locate middle rows and re-queried repeatedly — that failure is why the structure-aware strategy exists.
Single-event figures were measured in a development environment; session-level gains depend on how much of your workload is large tool output delivered directly to the model (write-file-then-read patterns bypass compression by design, at zero cost).
Installation & usage
Requirements: a running DeepSeek Harness (dsh) with its Web GUI, and pnpm on PATH. The web profile provides everything else the plugin needs (tools, webServer, React for the dashboard; spillStore is included in standard deployments — if it is ever missing, compression stays off by design).
Install
Run one of these commands — dsh plugin installs the package into the profile and activates its bundle layer automatically:
# from the npm registry
dsh plugin --profile web add dsh-plugin-save-token

# or straight from GitHub
dsh plugin --profile web add github:vibe-any/dsh-plugin-save-token

# or from a local checkout
dsh plugin --profile web add /absolute/path/to/dsh-plugin-save-token
That's the whole installation: no prompts to paste into the GUI, no dynamic-code authorization dialogs. Verify it's in the roster with dsh --profile web --dump-config | grep save-token, then restart the running dsh instance (ESM caches are per-process).
Removal: dsh plugin --profile web remove dsh-plugin-save-token.
Using it
Once installed there is nothing to operate: open Settings → Token Saver for the full panel, and look for the persistent live strip under the input box. Three toggles (Compress / Dedupe / Compact@120k) switch right on the panel. The panel and the strip follow dsh's language setting (Settings → General → Language: English / 简体中文).
Config defaults (the config: block of the save-token row in cordis.patch.yml; code fallbacks live in src/index.js)
| Parameter | Default | Meaning |
|---|---|---|
minBytes |
1400 | Minimum size for ordinary outputs to enter compression |
errorMinBytes |
6000 | Higher threshold for error output (leave debugging scenes alone) |
keepRatioMax |
0.72 | Byte-gate cap: compressed must not exceed 72% of original |
maxLines / headLines / tailLines |
240/140/80 | Window shape for ordinary long outputs |
tabularHeadRows / tabularTailRows / tabularStrideSamples |
60/40/50 | Retention and sampling density in table mode |
longLineChars |
420 | Head/tail truncation threshold for single oversized lines |
jsonlMinLines |
8 | Minimum uniform-object lines for the JSONL/NDJSON lossless route |
noticeFullTrailerCount |
3 | First N adopted compressions carry the verbose retrieval notice; later ones use the compact trailer (same id + locator) |
dedupeTtlMs |
600000 | Validity window for cross-turn dedup (fingerprints are byte-exact, so a longer window is information-safe) |
dedupeTtlOverrides |
{} | Per-tool TTL in ms; 0 disables dedupe for that tool (freshness-sensitive commands) |
compactAssistEnabled |
false | Compaction coupling master switch — off by default (see cache note below) |
compactBudgetTokens / compactCooldownMs |
120000/600000 | Absolute fallback watermark and cooldown for the compaction assist |
contextWindowTokens / compactWatermarkRatio |
0/0.85 | When the model window is known, the watermark is window × ratio instead of the absolute budget |
v2.2.0 behavior notes:
- Dedupe keys carry the owning session id and hash the FULL args/content strings (long shared prefixes can no longer produce false "byte-identical" stubs; two sessions sharing one process never see each other's stubs).
save_token_expandoutput is exempt from compression — unfolding a notice can never hand back the same elided preview again.- Lossless routes extended: JSONL/NDJSON logs, nested field groups (
pos{x,y}), keyed maps, and a depth-2 dominant-array search ({data:{items:[...]}}). Lossless wins whenever it passes the never-worse gates; the lossy elision candidate is generated as the gate-checked fallback before the line compressor, and lossy notices disclose exactly what was omitted. - Compression counters increment on adopted candidates (previously on attempts that the gates could still reject).
v2.3.0 cache-aware layer (bench evidence: ~90% of measured input tokens were provider cache reads, billed at ~1/30 of the miss price on DeepSeek):
- Compaction assist defaults to OFF and is repositioned as an anti-overflow measure, not a saver: summarizing 120k→40k tokens converts cheap cached replay into full-price input and breaks even only after ~60 further requests. Turn it on when sessions actually grow past the watermark; do not expect it to cut spend. The toggle and watermark are honest in the panel.
- The watermark prefers the last real billed input for the session (main requests only) over the heuristic estimate, and scales with the model window (
contextWindowTokens × compactWatermarkRatio) when configured. - Cache-hit sentinel KPI:
cacheRead/cacheWriteare metered separately and the panel shows the cache-hit percentage. If a future change tanks that number, it is saving tokens while silently raising real cost. - Online calibration: a per-model EMA of billed/estimated tokens (learned from real usage each request) corrects the avoided-token accounting — no bundled tokenizer. The compression token gate needs no calibration (the ratio cancels in that comparison).
v2.4.0 closing items:
- Dedupe TTL default 90s → 600s with per-tool overrides (
dedupeTtlOverrides,0opts a tool out entirely). - Error-line protection in plain-text windows widened to ±1 context line (25 anchors, adjacent anchors merged): a bare assertion line rarely explains itself; the neighboring test name / stack header is what saves a re-run.
save_token_expandsurvives eviction and restarts: an id→locator side index outlives the text cache, so a miss returns the spill locator (with a transparentspillStore.readTextattempt when the host offers one) instead of a dead end.- Top-level vs nested tool calls are counted on the panel — the nesting exemption currently skips compression for subagent-internal calls, and this counter finally quantifies that unexploited surface before anyone flips it.
How it works (30-second version)
tool returns ──► tools/post-execute (prepend)
             ├─ size ≤ threshold? ────────── pass through
             ├─ byte-identical within 90s? ─ spill original → replace with dedup stub
             ├─ JSON with uniform array? ─── TOON lossless re-encode (zero loss)
             ├─ JSONL of uniform objects? ── one TOON table for the whole log
             ├─ pipe/tab table shape? ────── stride-sampled window with line numbers
             └─ other long text ──────────── head/tail window + error-line protection
                      │  double gate per route: ≤72% bytes AND tokens strictly decrease
                      │  (lossless first; lossy elision is the gate-checked fallback)
                      ▼
             spill original to spillStore → inject [save-token #id] retrieval notice
                      ▼
every model request ◄── llm/stream metering (real billing + avoided tokens, per-model calibrated)
step boundaries ──► assist on AND billed > watermark? ──► compaction.compactIfNeeded('pressure')
All compression logic lives in src/compress.js (pure, side-effect free) and is pinned by the unit-test suite: npm test (node --test, zero extra dependencies).
Directory layout
dsh-plugin-save-token/
├── README.md             ← this file (English, default entry)
├── README.zh-CN.md       ← Chinese documentation
├── manifest.json         ← metadata + config defaults
├── package.json          ← npm manifest declaring dsh.bundle + ./client export
├── cordis.patch.yml      ← the bundle layer inserted into the profile roster
├── build.mjs             ← esbuild script producing lib/
├── src/
│   ├── index.js          ← Host half: waterfall hooks / orchestration / tool registration / API routes
│   ├── compress.js       ← pure compression brain (estimators, TOON tabular, gates, notices)
│   └── client/index.js   ← Client half: Dashboard panel + input-box live strip
├── test/                 ← node --test unit suite pinning the compression brain
└── lib/                  ← built artifacts (committed, so git installs need no build step)
    ├── index.js          ← bundled ESM host half (node)
    └── client.js         ← bundled client half wrapped in window.__ModuleLoader__.load({ id, factory })
Design red lines ("no dumbing down" promises)
- Reversible: failed disk write = abandon compression;
readandsave_token_expandoutputs are never processed (by-design exemptions). - Lossless first: lossless wins whenever it passes the never-worse gate; lossy elision runs only as the gate-checked fallback and its notices disclose what was omitted.
- Double gate: every replacement must prove itself "smaller in bytes AND cheaper in tokens," or it passes through.
- Error protection: high thresholds around failure scenes, mandatory retention of error lines (±1 context line).
- Cache-stable: compression happens once, at tool-result entry; history stays byte-stable afterwards, so the provider prompt cache keeps hitting (measured: ~90% of input tokens were cache reads at ~1/30 price, and 91.1% even in the heaviest dump-heavy episode). Replay-time rewriting of history is out of scope by design — it lowers the token meter while raising the real bill.
Related相关推荐
-
 MeteorNOX/DeepSeek-Balance-Whale-Widget
DeepSeek Harness(DSH)一只住在 DSH 界面右下角的小鲸鱼娘,帮你盯着DeepSeek账户余额。QQ弹弹,支持拖拽吸附、左吸附翻转、数字滚动动画,随界面自动启用,建议直接喊来你的dsh安装
-
 Han-1413141/dsh-cost-meter
DeepSeek Harness session cost meter plugin: session/daily cost, budget, history, OpenCode Go quota, official & custom-pr…
-
 zh667/TokenLedger
Relay-site attributed token usage for DeepSeek Harness — zero config, no credentials
-
 wssfk12138/dsh-damage-pulse
DeepSeek Harness Token 余额监控插件:鲸鱼娘待机/扣费/复苏动画、峰谷计费、连续扣费飘字与会话费用统计。
-
 Ychris12138/dsh-usage-stats
Provider balances, subscription quotas, and token-usage analytics for the DeepSeek Harness Web GUI (dsh web).
-
 Aisland-SJL/dsh-usage
🌊 Persistent dock & fully-customizable balance/usage panel for DeepSeek Harness — activity heatmap, dual-channel compar…
-
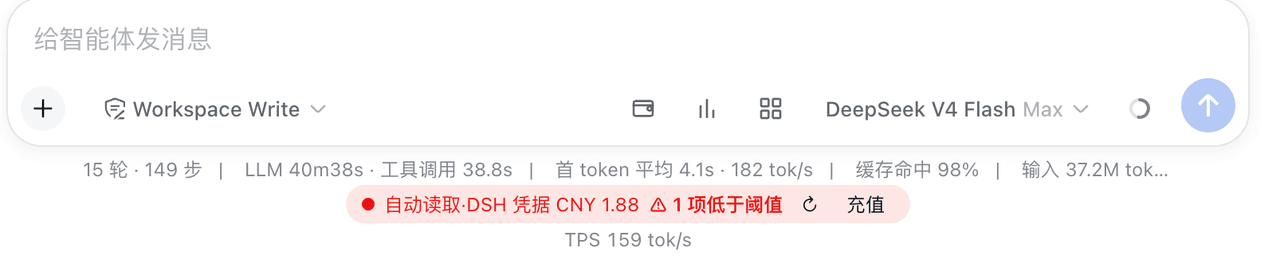 yxxbc/dsh-balance-plugin
deepSeek 余额监控与用量统计(DSH 动态 Cordis 插件):余额监控 · 官方充值入口 · 用量统计 · 三方插件管理
-
 slywalker2006/dsh-passwords
Server-grade gateway that turns DeepSeek Harness into a multi-tenant platform: remote access + auto HTTPS, subuser permi…